At Summer Camp We Stress Tested Policy Implementation So You Can Too
Even the best-designed policy rests on assumptions about who will staff it, how it will be funded, whether the responsible institutions have ever coordinated, and if the goals are achievable. Those assumptions usually go unchecked until a program is already struggling, stalled by capacity bottlenecks, overlapping authorities, and other predictable implementation problems.
To dig into these questions and start to better prepare the policy design field for delivery, the FAS Center for Regulatory Ingenuity launched State Capacity Summer Camp, a workshop series that tests our assumptions about how policy gets implemented, where it breaks down, and what it takes to get from bill signing to on-the-ground results. Through tabletop simulations and interactive discussions, participants work through the most common implementation failure points: unclear outcomes and accountability; thin institutional capacity; policy design risk; empty chairs in drafting, execution, and evaluation; fragile trust; complex hand-off points; and weak feedback loops. Participants build the habit of deeply integrating implementation considerations from a wide range of perspectives into policy design and leave with practical tools for tackling unforeseen capacity and coordination challenges. And of course, there’s ice cream.
We developed a toolkit for asking these questions about any policy before it launches: the Pre-Implementation Stress Test Checklist. And now, we’re sharing it with you – to test, to tailor, to play with, and to build habits that integrate delivery considerations as soon as you have a policy idea.
Who is this checklist for?
Anyone who’s written a policy, program, or regulation and can still change it before it launches — or is at an inflection point where the direction or details of implementation can be changed. This checklist is designed for any level of governance (city, state, or federal – certainly tailor it for your use) and any policy that assumes implementation actions will take place, particularly out of sight or control of the drafter.
What is this for?
To test the assumptions, transitions, and expectations most likely to impact or break policy delivery across seven categories, and to focus scarce time on what’s manageable:
- Outcomes and Accountability: Is there a specific, evidence-based outcome this policy is meant to achieve — not just a process to complete? Is there a named owner who faces real consequences if that outcome isn’t reached?
- Institutional Capacity Assumptions: Does this policy assume institutions have the capacity, coordination, and willingness to deliver it? Have those assumptions actually been tested — or are they just being taken on faith?
- Policy Design Risk: Does the policy’s text or policy relationships create risk, through ambiguity, specificity, red tape, or outside veto exposure?
- Empty Chairs: Is there a group affected by this policy who wasn’t consulted in its design — and who might know something the drafters don’t?
- Trust and Legitimacy: Do the people and institutions affected by this policy trust that it’s fair — both how it was designed and how it’s being carried out?
- Hand-off Points: Are there points where authority, information, or responsibility transfer between institutions? If so, is each one set up to work — clear ownership, functioning information flow, no legal barriers in the way?
- Feedback and Learning: Is there a mechanism that will show, within the first 60-90 days, whether this is on track? Is there someone who is empowered to act on what it shows?
How to use it?
The checklist helps you identify key stakeholders and institutions, work through a policy deep dive, and understand spheres of influence.
Explore the Pre-Implementation Stress Test Checklist here. And tell us what you think!
Interested in learning more about State Capacity Summer Camp? We’re gathering around the campfire again this fall to continue learning and sharing best practices. Email us!
Leveling the Analytical Playing Field for State Regulators
How a federal technical and talent hub could strengthen state energy affordability and deployment efforts
The Problem
State regulators are making increasingly complex, high-stakes decisions about the electricity system: The confluence of electricity demand from data centers, manufacturing, and electrification is driving utilities to propose major investments in infrastructure. Public Utility Commissions (PUCs) must evaluate these decisions while balancing state priorities and weighing reliability/affordability for ratepayers.
Public Utility Commission (PUC) analytical capacity has not kept pace: Many commissions have limited access to specialized expertise in modelling and forecasting analysis that allows them to make independent, informed decisions with public funds. The challenge is not simply the number of staff, but whether commissions have the expertise and tools to independently evaluate the sophisticated models and assumptions underlying utility proposals.
Utilities can have substantially greater analytical resources than the regulators overseeing them: Utilities and other stakeholders can invest heavily in proprietary consultants and models while PUCs may rely on utility-provided analysis or procure outside expertise on a case-by-case basis. Commission-retained consultants can provide valuable analysis but do not necessarily build durable institutional capacity.
The talent pipeline of people who are trained to work on public interest analysis—and want to—is limited: Even if all PUCs had the funding to support greater staff capacity, they would struggle to find experts to hire. There are too few people with the right expertise who are not already working for utilities or their consultants. Even when these experts are available, it can be difficult for individual commissions to compete with private sector employees on salary, work location, and benefits.
The Opportunity
Congress can build on existing DOE and national-laboratory technical assistance programs to create a pooled capacity hub for state regulators. The hub could provide (1) shared staff to rotate between commissions, (2) a prestigious brand and training program to attract new talent and build the pipeline, and (3) analytical firepower for PUCs to use for free. Existing programs, like the State Technical Assistance Program housed across four labs, demonstrate the value of connecting state regulators with national-laboratory expertise. A dedicated national resource could provide more sustained analytical support throughout major utility planning and regulatory cycles.
Policy Recommendation
Congress should establish a Modeling, Analysis, and Technical Talent for Energy Regulation Hub (MATTER Hub) within the Department of Energy (DOE). Administered by one or more national laboratories, the program would:
- Build a dedicated multidisciplinary surge team with expertise in ratemaking, resource planning, modeling, load forecasting, and the latest innovations in grid technologies and strategies (e.g., virtual power plants, alternative transmission technologies, surplus interconnection, etc.). Make the team available to detail to PUCs who need additional capacity to complement full-time PUC staff. Make compensation competitive with utility positions and utility consultants to attract strong talent.
- Develop and maintain shared analytical tools that commissions can use (either directly or with the help of the detailed surge members or national lab staff) to evaluate utility proposals, model alternatives, test assumptions, and conduct proactive work. Rather than requiring every commission to build its own modeling infrastructure, the federal resource could provide a shared analytical foundation.
- Build a talent pipeline by training new experts in utility oversight and ratemaking, providing a landing place for recent graduates to find a job in public interest utility regulation, and partnering with universities to increase awareness and interest.
- Strengthen state capacity over time by training PUC staff and facilitating peer learning among commissions.
The program would complement—not replace—permanent PUC staff and existing state and federal technical assistance programs, with DOE coordinating with NARUC and other groups to leverage existing capabilities and avoid duplication.
What Congress Should Do
Some good ideas for supporting PUC capacity are already swirling, including the newly introduced State Energy Oversight Act from Representative Tonko that would provide formula grants to state PUCs to expand commission capabilities and establish a DOE technical assistance program for PUCs.
In addition to formula funds and technical assistance, Congress should authorize and appropriate dedicated funding for DOE to establish a hub for shared resources and staff that PUCs can draw upon directly, including modeling capabilities and experts in key topic areas that can be seconded to PUCs for surge capacity. The hub could live at one or multiple national labs, perhaps Lawrence Berkeley National Laboratory, the National Lab of the Rockies, and the Pacific Northwest National Laboratory. Congress should provide approximately $30 million annually for five years to cover staff, tool development, and training. The program should include safeguards to ensure that assistance is provided at the direction of state commissions and remains independent of utilities and other parties.
Are We Guessing Well or Knowing Well? Evidence Gaps in R&D Institutional Design
Decisions made based on instinct, analogy, and a strong theory of change have a way of becoming retroactively reframed as evidence-based once they work out. That’s part of why “well-reasoned” and “evidence-based” are often used interchangeably in policy conversations – and why it can be hard to tell, looking back, which parts of our policies, programs, and institutions were actually designed on rigorous grounds and which just got lucky. The distinction becomes more important than ever in moments of disruption; design features that were never truly grounded in evidence can become precedent, and underexamined ones get a pass because they haven’t failed in a visible way.
This isn’t an abstract worry. In early July, FAS convened a group of experts for a design exercise, imagining the federal R&D institutions they would build if they could start from scratch. The exercise was designed to help answer the questions: Are the institutions we have today fit for purpose? If not, do we know enough to redesign them well? We found that the answer to both of these questions is no – not because good ideas are scarce, but because the evidence base underneath institutional design isn’t quite as mature as most confident policy proposals assume. The design of federal R&D institutions as they exist today is part inherited guesswork and part accumulated “stop energy” , layered so many times over that it’s impossible to remember what we’ve rigorously tested (if anything). As we look toward the future, we have a chance to design better – here’s how.
Where are the gaps in our current evidence base?
We’ve made strides in understanding what our R&D institutions are producing: patents, citations, journal articles, and more. But hitting every metric can happen by chance, and doesn’t guarantee impact.
Our existing evidence base has a few structural problems:
Bias in the metrics themselves. The limited set of metrics that the current literature on the ROI of R&D relies upon show the survivors, not the failures. We know a lot about the DARPA programs that produced GPS and the internet; we know much less about the DARPA bets that didn’t pan out; the evidence is even thinner on other agencies that tried a similar model. These metrics are also limited in what they can tell you about impact – some research might not lead to a high-impact journal article, but might help a specific community solve a big problem or provide training for early-career researchers, and that might be just as valuable.
We’ve written much more about the types of questions the research community should invest in answering, and the outcomes they should seek to measure, to have the type of robust understanding of the impact of R&D spending decision-makers need today. Without a clearer picture of the impact of our current institutions’ approaches – i.e., an understanding of what works and under what conditions – we run the risk of replicating approaches that won’t drive impact.
Findings may not generalize. Differences between design models clearly matter — the portfolio-driven approach of ARPA models produces different outputs than investigator-initiated funding’s broader model. And different agencies that have implemented ARPAs have employed different approaches to their talent model, decision-making, and timelines for funding. But knowing that the models differ isn’t the same as knowing, rigorously, which conditions produce breakthroughs versus reliable, incremental progress. A mechanism that works in one scientific domain, funding environment, or political moment doesn’t automatically transfer to another.
A limited comparative infrastructure. Institutional design knowledge is strikingly under-documented, with few good manuals and little (but not zero!) cross-case comparison. Much of the literature on key ingredients in institutional design, like hiring authorities, describes the available options or relies on anecdotal evidence rather than rigorous evaluation of the impact of various approaches. Toolkits and templates have started to emerge, such as The Institutional Architecture Lab’s guides for new and renewing institutions and the Overedge Catalog of innovative research organizations. But the conversation at the workshop showed us that these resources are still more limited than is needed, and the resources that do exist aren’t yet relied upon by those who are imagining the future of R&D institutions. If the opportunity to design a new R&D institution emerged today, it would be designed largely from analogy and instinct, not from an accumulated, testable body of knowledge.
The potential implication of these evidence gaps becomes more consequential when you look at how institutions actually make decisions day to day. For example: in one of the workshop’s exercises, participants found that funding instruments usually get locked in by habit, not fit – program managers default to whatever mechanism they’ve used before, and there’s rarely real capacity to reassess mid-course. The gap isn’t just a missing tool. It’s a missing muscle for choosing, and re-choosing, deliberately. That’s just one example, but it’s exactly the kind of decision that’s usually defended after the fact as evidence-based when it works out, when it was really just default behavior dressed up in retrospective justification.
What would actually closing the gap require?
The answer isn’t to slow everything down until perfect evidence arrives — that evidence may never fully arrive.
But there’s a few concrete moves that can be made starting today:
- Document design logic as it happens, not after the fact. The same legibility gap that leaves institutional design under-documented also means hard-won lessons from any given redesign effort risk being lost before the next one starts. Capturing the reasoning behind decisions – not just the decisions themselves – should be its own deliverable. New technological advances make it easier than ever before to continuously synthesize data and evidence as it emerges, which could give institutional founders a greater understanding of what design decisions have been made in the past, why those decisions were made, and the impact they led to. That data and evidence should be a key input into institutional design conversations, such as agency reauthorization.
- Build the comparative infrastructure that future institutional founders will need. Simulation, cross-case comparison, and AI-assisted tools could let designers stress-test structures proposed designs before committing to them, rather than relying on analogy to a handful of famous examples. For example, the Institute for Progress’s Atlas of Innovation is a new tool that could offer needed insights on how different funding instruments work in practice, or new approaches like digital twin technology could help simulate the impact of different design decisions.
- Design for evaluability and course-correction from day one. Rather than assuming the founding design is correct and static, new institutions have a rare opportunity to build in real feedback loops and the flexibility to course-correct, treating the initial design as a hypothesis rather than a final answer. In the R&D context, proposed metascience units are a promising way to tackle this – but if, and only if, mechanisms are constructed to ensure that the evidence they generate has a meaningful impact on decision making.
Temper confidence, don’t abandon action
None of this is an argument for paralysis; Americans deserve institutions that produce high-quality R&D. It is an argument for being honest about the difference between “well-reasoned” and “rigorously evidenced”.
Some tensions in institutional design – autonomy versus accountability, curiosity versus utility, efficiency versus equity – aren’t problems to solve, just permanent features to navigate. The evidence gap is like that too. It’s not fully going away before the next round of decisions gets made. The best available response isn’t to wait for certainty that may never come, but to be honest about how much of the confidence behind any given proposal is actually earned – and to build institutions flexible enough to find out they were wrong.
What Survives the Trip From Blue-Sky to the Real World
No institution gets built on a clean sheet. Every new institution inherits something – existing incentives, existing staff, decades of prior investment that shaped what’s possible. A new Advanced Research Projects Agency (ARPA)-style agency has a foundation partly because of the Defense Advanced Research Projects Agency (DARPA) model that came before it and the foundational research funded by more traditional R&D institutions that makes its agenda possible. A coordinating body proposed today would inherit the turf, budgets, and statutory authority of whatever agencies already touch that problem. A darker version of this premise is that while market incentives may clear out failed models in the private sector, in government very little forces that sort of reckoning, so institutions built for a 1960s problem are still standing when problems of the 2020s show up, wearing their old habits and assumptions.
Federal R&D faces a particularly stark version of this challenge. The basic architecture of how the federal government funds and fosters science, the peer review system, the relationship between agencies and universities or labs – all of those have roots in Vannevar Bush’s post-war vision. This (at the time) radical and successful system was not built for some of today’s disruptions, like AI acceleration of research pipelines, the changing role of the private sector, vastly different legislative-executive roles, and an increasingly tangled federal coordination architecture. In the 80 years since, we’ve layered, worked around, bloated, and streamlined this inheritance, but have not really made an effort to start from scratch.
That’s what makes blue-sky thinking exercises valuable. Strip away the inheritance of the past for a day and people can make unencumbered choices on decisionmaking, feedback loops, talent models, innovation, coordination, resource access and allocation, and more. Most institutions never get a chance to make these choices on purpose. Left alone, a bureaucracy will choose stability over exploring renewal almost every time, whether or not the status quo is working, because nothing inside the system forces the other choice.
FAS ran such an exercise in July, pulling together founders, government-capacity practitioners, academics, and metascience researchers in groups that each imagined a new R&D institution from scratch around a specific real-world problem. They made concrete decisions on governance, instruments, talent, and learning rather than describing aspirational values, pulling together institutions focused on topics from housing affordability or a federal grand-challenges portfolio.
The exercise itself was not the hard part (or at least, not the hardest part). Give a group of smart, experienced people a blank sheet and a real problem, and they’ll design something better than what exists today. The real design challenge starts the moment you try to put ideas back into a world full of prior claims, getting any of the great ideas generated into a bill, an agency reorganization, or a budget request. From this exercise, we think there may be strong candidates worth breaking the hold of prior models: seven groups worked through seven unrelated problems with no way to compare notes, and a few of the same decisions still showed up across the designs. As we consider future R&D institutional design opportunities (from NSF reauthorization to relevant planning for future presidential administrations), these are worth taking on the trip from blue-sky to reality.
What we learned from the designs
We asked groups to surface what’s broken today and the critical ingredients in future R&D institutions: instruments, credibility systems, public engagement, talent models, founding decisions. They took those diagnoses, which highlighted challenges in agility, balancing tradeoffs, superficial public engagement, lax accountability, and used a basic rubric to build something new and aspirational. Here are the themes that showed up again and again across groups tackling different challenges.
- R&D coordination problems don’t get solved by convening power alone – they get solved by convening power PLUS authority.
This was the most consistent thread across institutional designs, building on a diagnosis that critiqued poor coordination among agencies with overlapping science missions and emphasis on designing institutions around mechanism rather than the mission or market failure they are meant to solve. One group built their entire proposal around granting real coordinating authority to hold other agencies accountable; their design was explicitly based on the premise that no single existing agency owns “grand challenge” R&D problems, and the agencies that touch them are too siloed to solve this on their own. Another group reached the same conclusion from a different angle, proposing to centralize innovation services for federal R&D that are currently fragmented across delegation and coordination, backed by continual dedicated funding and maximum hiring authority. A third group wanted to build a “new credibility/adaptation layer” and described its function as closing feedback loops between the agencies that fund research and the agencies that would act on its findings.
What each of those groups said, with a slightly different twist, is that when tackling cross-agency alignment and coordination, the missing ingredient wasn’t a body that could bring people to the table, but one that could make a decision stick once it got there. That’s a meaningfully different task than “more coordination”, which is often invoked for purposes of transparency or as advisory conversations to tee up recommendations. Groups wanted to imagine what it looked like when there is real authority to force choices, hold other agencies accountable for outcomes, or centralize functions that are currently scattered across delegation and hand-offs – the kind of authority that can survive a disagreement.
Notably, none of these models turned to existing center-of-government bodies (or other intra or interagency models) to take this role. Andrew Greenway highlights this feature in his work on creative destruction, recognizing that task-force style bodies in the UK are most successful, deliberately built outside the host agency’s normal chain so they couldn’t be smothered by its process, then given real authority to bind decisions rather than just recommend them. Writing with Jen Pahlka, Greenway also notes that before the Consumer Financial Protection Bureau (CFPB) existed, seven separate agencies nominally held pieces of consumer protection, and none had it as a primary mission; consolidating that fragmented authority into one body with a clear mandate let it return more than $21 billion to consumers.
One useful exception: sometimes “coordination” can mean linking incentives, not designating governance through a single authority over everyone else. One group split the R&D pipeline into three separate entities – discovery, application, and commercialization – linked by shared governance and co-ownership rather than a hierarchy. In their design, profit generated from downstream success flows back to whichever entity originated the science, so nobody has a reason to let a good result die at the handoff between stages. This offered a different answer to the same problem the authority-based designs solved: instead of one body with the power to make a decision stick, this design pointed all of the entities’ interests in the same direction so that hierarchy wasn’t the only thing holding it together.
Takeaway for the trip: Goodwill and convenings are ingredients but insufficient for effective coordination of federal R&D power; what experts reached for was authority to set direction and make it stick, or incentives to make cooperation the default. Hiya Jain, Stuart Buck, and Aishwarya Khanduja make an intersecting point in their new essay on taxonomies of R&D organizations: two organizations can be identical on funding, timelines, and who they’re serving, and still produce completely different results depending on nothing but how decisions get made.
- Instruments should be matched to where a problem sits in the R&D pipeline, not a single default tool.
Today, R&D funding instruments are often set by habit and comfort, rather than fit – a key diagnostic of this exercise – with little inside-government capacity to stipulate what works or to propose shifts in approach. These break down in predictable ways when science moves faster than the plan anticipated, like cooperative agreements that don’t fit commercialization or milestone-based contracts that break down under R&D uncertainty, driving constant contract modifications to keep up. To address these limits, one design treated the choice of funding mechanism as something that should shift as a project matures — grants for early discovery, more flexible investment vehicles once there’s something to build on, a different structure again once the goal is commercialization or deployment — rather than picking one instrument and forcing every stage of a problem through it. Their approach overcomes the square-peg-round-hole instrument challenge by letting their institution ask “which tool fits this specific point in the process,” with the handoffs between stages treated as seriously as the stages themselves.
Most of the other designs didn’t formally stage instruments this way, but still resisted restricting themselves to a single funding tool. Their logic was that the tool should follow the problem rather than the other way around – for example, building a portfolio that explicitly seeks to make investments on different time horizons or that uses different funding instruments depending on the purpose and end-user of the research.
Takeaway for the trip: an instrument chosen out of habit isn’t neutral, it’s a bet that this problem looks like the last one. The Institute for Progress’s Atlas of Innovation is a great start to this challenge, routing funders to one of thirteen mechanisms by answering three questions: how well-defined the problem is, what a solution would look like, and which team is positioned to build it?
- Public input shouldn’t just be a feedback mechanism; it should be a design input, too.
The diagnosis of current public input mechanisms into R&D was a vociferous failing grade; from notice and comment, to community advisory bodies, to efforts at transparency – most were seen as well-intentioned box checking rather than efforts for legitimate engagement. The workshop repeatedly came back to the theme that improving legitimacy and effectiveness in the eyes of the public is vital – and currently broken. Effective engagement lives upstream of today’s formal input mechanisms, both as a means to effectively inform public science and to increase the legitimacy of public investments. If current mechanisms were once well-intentioned, they’ve suffered the fate of many other institutional innovations, calcifying into a procedural or compliance check rather than a value.
As a consequence, the more interesting designs didn’t propose better PR or storytelling that explains funding decisions to the public after they were made. Instead, they asked how to let public and community input shape which problems agencies should tackle and how research got framed in the first place. That’s meaningfully different from most of our current approaches that embed and elevate the same voices at a point too late for useful input. For example, one group explicitly said the biggest departure in their design from what R&D institutions have today is “giving community feedback real influence over problem choice and research design”; another proposed a review process where individual project choices rely on both local/community impact and scientific expertise.
Takeaway for the trip: public input isn’t neutral: without deliberate design, the loudest or best-resourced voices, such as business interests, might crowd out everyone else, so the mechanism itself has to be built to ensure it gathers input from a representative sample.
- Talent is the design variable that does the most work – and the challenge is far more sophisticated than hiring fast.
“Nobody is in charge of innovation and anyone who claims to be probably isn’t.”This sharp diagnostic comment from one participant highlighted the root of the government’s R&D talent problem. Innovation comes from motivated, curious people incentivized to learn in a system that roots for them, not from an organizational chart, and federal agencies have struggled to find or support that kind of person.
The recurring throughline in designs wasn’t simply “hire good people;” it was a specific kind of comfort with ceding control and creating systems that let them thrive: leaders willing to hire people who know more than they do and are empowered to act decisively and creatively. Several groups proposed a model where program managers were empowered to move across agency lines (so-called “boundary spanners”) rather than staying in a lane; others proposed hiring staff whose job is explicitly to translate between worlds (science and market, or science and community) rather than sit inside just one of them. Pahlka and Greenway make a related point about boundary-spanners: the strongest founding teams pair insiders who chafe against institutional norms with outsiders drawn by the mission, since too many career officials will stifle disruption and too many people who don’t understand how bureaucracy works can be just as fatal.
Hiring the right people (and the appropriate mechanism to do so) isn’t the only key concern. This sort of talent is both rare and challenging to entice into overly bureaucratic roles, necessitating not just rethinking of role definition but growth, cross-training, and incentives. Continuous learning for program managers and other key staff to ensure they don’t become entrenched in the approaches that existed when they arrived is just as important. Superstar talent will struggle to stay engaged on a junior varsity field – DARPA’s reverence for program managers only works because the agency can act fast around them, not wasting a talent recruit on a six month hiring process or multi-month decisions processes.
Ultimately, this means caring about talent in ways government has struggled with, particularly at R&D institutions: investing in people willing to take risks, in the people who build the infrastructure that lets them take those risks for public impact, and in the recruitment infrastructure that finds both.
Takeaway for the trip: government keeps trying to solve challenges related to innovation talent as a hiring problem when it’s actually three problems stacked on top of each other, whether the right person exists, whether the system is built for them to succeed, and whether anyone was looking for them in the first place. Fixing only the first one is why so many great hires become average or former.
- Political durability should be scoped and designed for up front.
Publicly funded science gets held to short-term political scrutiny that other government money escapes. Political cycles move faster than science can absorb, which means priorities swing before results are even in, and the accountability hits hardest on exactly the kind of research that takes the longest to pay off.
R&D institutions get a similar problem: new institutions with new leaders or missions get more carve-outs, room to maneuver, and the halo effect from overseers; older institutions are stuck with residual procedural barriers and longstanding scrutiny.
Rather than treating the risk of political turnover, earmarks, or administration changes as an implementation problem to worry about after the institution existed, several groups treated it as a first-order design constraint. That shows up as a deliberate push for insulation and independent authority in some designs, and as open, unresolved questions about whether existing structures (the National Science Board, existing agency directorates) are the right vehicle for that durability in others. For example, one group proposed a coordinating body where governance would be led by career staff from various R&D agencies rather than political appointees.
Takeaway for the trip: Political change and risk isn’t a threat to manage, it’s a design spec; realistic considerations around insulation, governance, and succession need answers before the institution launches.
- The most common “biggest departure” from what we have today wasn’t a new tool, it was shifting power.
Ask each group what its design changed most from how things work today, and the answers split by which direction power moved. Three groups pushed power down, toward the communities and end-users closest to a problem: real influence over problem choice, devolved leadership, feedback loops built into the structure instead of added on. Two more pushed it up, into a coordinating authority that doesn’t currently exist and would need real teeth over agencies that already do.
The split tracks back to two different diagnoses from the day before. The groups pushing power down were answering the public-engagement critique directly: existing mechanisms, comment periods, advisory boards, oversight, all operate downstream of the decisions that actually matter. The groups pushing power up were answering the coordination critique: agencies that touch the same science don’t coordinate well, and nobody currently has the authority to make a cross-agency call stick.
It would be easy to treat these patterns as interesting but premature – worth revisiting once the right big legislative vehicle comes along. Founding moments are the point of maximum leverage in an institution’s life: decisions about mission, succession, culture, and evaluation made at the outset shape an institution for decades, yet rarely get made consciously. But waiting for a hypothetical clean-slate moment misses the actual openings that exist right now, in whatever form they take – and by the time a bigger opportunity arrives, the important decisions made at a smaller one will already be locked in, for better or worse.
“Right now” doesn’t have to mean a brand new institution. Pahlka and Greenway lay out a real range of options between doing nothing and starting from scratch. Universal Credit’s turnaround happened entirely inside the UK’s existing welfare department, with new leadership and a new mandate. Colorado’s digital service took a middle path, planting a new team inside a broken agency until the new way of working displaced the old one outright. New institutions like NASA or DARPA are the right call when no existing agency could plausibly take on the job, but they’re one option on a spectrum, not the only lever available to whoever’s holding a smaller opening right now.
Takeaway for the trip: before you design anything, consider which failure modes scare you; and match your ambition to the transformational opening you actually have.
Some tensions aren’t problems to solve. They’re just what you navigate.
Four tensions sit underneath almost any institutional design, and none of them get solved, only managed. Curiosity versus utility: research pursued because it’s interesting, versus research aimed at an immediate need. Political accountability versus scientific autonomy: the demand for relevance against the independence that lets evidence lead somewhere inconvenient. Efficiency versus equity: doing the most with limited money against reaching whoever needs the work most, not just whoever’s easiest to serve. And an organization’s stated mission versus what actually motivates the people inside it, which drift apart more often than anyone wants to admit.
The toughest version of all four shows up at the budget level: full-cost accountability versus flexibility. You can have rigorous, fully-costed oversight, or you can have room to move fast and change course; wanting both in full is how institutions end up with neither.
Groups refined these tradeoffs to understand what will always be a challenge; they’re not a checklist to clear before a design counts as finished. The question isn’t how to solve the tension but which side you’re choosing on purpose, and whether the people accountable for the institution know that’s the choice being made.
Where do we go from here?
The type of overhaul that results in a brand-new science institution may not be on the table anytime soon, but plenty of the ideas generated by groups are still ripe for implementation today.
Here’s where we can meaningfully learn from their designs to improve our existing institutions in the near-term:
Increase the capacity of existing coordinating bodies to effect change. The number of groups that proposed new forms of convening and coordination across R&D agencies is a clear diagnosis that our existing bodies, such as the National Science and Technology Council (NSTC), aren’t working. And frankly, it’s not their fault: the Congressional Research Service recommended in 2023 that Congress meaningfully interrogate the resource constraints on the Office of Science and Technology Policy. Ensuring that existing policy coordination committees are appropriately resourced and have the capability to provide actionable recommendations to agencies might solve some of the problems that groups pointed to without requiring a full overhaul.
Experiment with new funding approaches. The recently announced X-Labs program at NSF is an important proof point that agencies can try out new ways to fund research that are explicitly designed to be fit-for-purpose. This is an opportunity to try something different and learn what is working in the process. Other R&D agencies should think just as creatively – for example, the Department of Energy released and implemented updated guidance in 2023 that clarifies how its Other Transactions (OT) Authority can be used; DOE should continue to expand its use when the flexibility of OTs is a better match than traditional grantmaking strategies, aligned to workshop groups’ recommendations around instrument mix.
Incorporate more public input. Grantmaking agencies can adopt approaches that allow a broader set of voices to influence grantmaking strategy. This can take a number of forms – from making requests for information about new research programs more accessible to new types of research awards. One compelling strategy to learn from is the Institute of Education Sciences’ recent announcement of changes to how it supports research “Network Hubs”; while these have historically served as ways to connect researchers, they will now be asked to conduct activities that allow them to better understand Americans’ research needs.
Leverage live policy windows. While agencies can do plenty without a legislative overhaul, there are some upcoming opportunities to enact some of the more dramatic changes groups pointed to – in particular, the National Science Foundation’s current authorizing legislation will expire next year. This is a unique opportunity to holistically consider whether NSF’s current design is well-aligned to its three-prong purpose.
As legislators consider priorities for reauthorization, there are a few specific design areas they should explore:
- Recommitment to Catalyzing Foundational Research: Aligning on the purpose for NSF, with a primary focus on building a foundation, but not constraining the agency to grant-only funding mechanisms and preserving the Directorate for Technology, Innovation, and Partnership (TIP)’s focus on accelerating innovation.
- STEM Workforce Mandate: NSF could take a more strategic approach to its role in building the STEM workforce of tomorrow. For example, it could house a workforce intelligence program that helps explore the specific needs of emerging S&T fields. Building upon existing approaches like the Rotator program, NSF might also adopt more use of personnel mechanisms that allow them to bring in specific expertise when it’s needed, including some of the more translational roles that many groups proposed in their designs.
- Agility and Flexibility: This might include devolved authority over grantmaking, beginning or expanding programs that give program officers greater discretion in awarding funding, similar to ARPA models or “fast grants” that accelerate the pace of grantmaking. Additionally, NSF reauthorization could expand Other Transactions authority to extend agency-wide beyond a single directorate (currently, the Technology, Innovation, Partnerships directorate) as a mechanism for enhanced flexibility.
Fix what accountability truly measures. R&D spending gets judged by a stricter and stranger standard than most government money. It faces short-term political scrutiny that other spending largely escapes, on timelines that don’t match how long real research takes to pay off, and is tracked more by geography rather than by outcome or impact, so even when something is working, there’s no clean way to show it. The fix isn’t asking science to move faster, but instead evaluating it on a timeline and with measures that match how the work happens in reality, and tracking it by what it produces and the impact that work can have.
What’s haunting these designs but never gets named directly: peer review. The workshop’s diagnosis flagged that credibility systems are built for accountability and transparency, but poorly equipped to reward agility or value negative results. This resurfaced almost as an aside in the workshop’s conversations, where one group noted flatly that traditional peer review “drives funding decisions toward safe, incremental research” and needs to reorient toward risk management instead. No group built a fix into an actual institution. But look back at what the other recommendations require: instruments that shift with a problem’s stage, talent willing to take real risks, coordinating bodies with authority to back ambitious bets. All of it still runs through a review process built to reward a safest version. Fixing peer review isn’t a fifth item on this list so much as a thing that determines whether any of the others work.
What doesn’t survive the trip?
Not everything blue-sky thinking produces will translate cleanly. The same groups that worried about political resilience were also, implicitly, wrestling with a harder tension: the least-friction option in institutional design tends to produce the worst result, and building real coordinating authority is inherently high-friction. It means taking on existing agencies’ turf, existing appropriators’ preferences, and existing staff’s incentives. A design that looks clean on a whiteboard because it assumes away that friction probably isn’t quite ready for a policy window. It is impossible to resolve all tradeoffs in shaping and incentivizing public science and anyone who tells you otherwise is selling something. Tough choices will always need to be made.
The value of an exercise like this was never the designs themselves (though they are impressively detailed for the hour we gave groups to come up with them). It was building a sharper, shared vocabulary for what well-designed R&D institutions actually require – coordination with real authority, the right talent and leaders, feedback loops built in from the start – and testing that vocabulary against problems specific enough to force real tradeoffs.
The next step is doing the harder work of testing those same patterns against whatever windows are open, one at a time, wherever they show up – a reauthorization law due for renewal, a new agency proposal with room to build these patterns in from day one, or simply an existing agency choosing, when its own authority makes it possible, to pursue new funding strategies and build in real feedback loops without waiting for a bill at all.
An open letter to the new NYC PIT Crew
When government works well, people barely notice; it’s just easy. This is what New Yorkers deserve—a responsive government is not only about good policy; it’s about the ability to deliver public services that are accessible, simple to navigate, and meets their needs. We are practitioners who have built, led, and supported successful digital service initiatives around the country, including leading IRS’ Direct File—which is why we are so encouraged by the launch of the NYC Public Interest Technology (PIT) Crew.
This initiative can improve services for millions. We are excited to see this investment in:
- People-centered delivery. The fastest way to build trust is to make government easier to navigate—trust is built or broken at the counter, on the phone, in the app that either works or doesn’t. Treating service delivery as a priority and putting people’s needs at the center will help the PIT Crew deliver for New Yorkers.
- Building lasting government capacity. The most responsive governments invest in their own people. Building in-house expertise in product management, engineering, design, and data creates the internal capacity to improve services, adapt to change, and reduce costly outside vendors—building public services that are by and for New Yorkers.
- New ways of working. The best digital service teams don’t just build better technology, they rethink how government works by organizing around the needs of people rather than the boundaries of bureaucracy. This is a new model for government—and what’s being built in New York can help cities around the U.S. learn how to deliver better services.
Recently, the Federation of American Scientists and the Beeck Center for Social Impact + Innovation at Georgetown University talked to more than 100 government leaders who built and led digital service initiatives across local, state, and federal government. Their experiences revealed important information about the conditions that allow public interest tech projects like this to create lasting impact.
The announcement reflects many of those lessons already. We hope you’ll consider several principles that are essential to radically redefining the relationship between people and their government:
- Set a standard that changes expectations of government. Take a page from the work of Direct File, which increased trust in the IRS by 86%—don’t just build services that are better than before, build services that are so intuitive, accessible, and reliable that New Yorkers expect every interaction with government to meet the same standard.
- Move beyond agency siloes. Organize around services, not agencies. People come to government at different moments in their lives: a new baby, a lost job, a business they’re trying to start. The most effective digital service teams organize their work, including funding, staffing, and operations, around the outcomes that public services are trying to achieve.
- Empower and hold accountable service leaders. The only way to scale your impact is to empower teams and hold them transparently accountable. The highest performing organizations succeed because a single team is empowered to own a service end-to-end and answers for its success. Giving teams clear responsibility for outcomes—paired with the authority to actually make changes and tough choices—creates the conditions for faster, better, and more durable results.
- Live or die by good gov-ops. Move to outcomes-based everything—from hiring, to procurement, to budgeting and, of course, product launches, taking an agile, outcomes and deadline-driven approach will ensure delivery happens on time. We are encouraged by the COGE and believe a similar, challenging approach to all types of policies and processes should be taken.
- Go big or go home. Be bold enough to become the model. You have the opportunity to not just improve New Yorker City’s services, but to create open, reusable approaches—from open source public options to services with 100% uptake—that raise the standard for governments anywhere.
This is a tremendous opportunity to redefine what people expect from government, and in doing so, inspire cities across the country to raise their own ambitions. We are excited to see this initiative lead the way and look forward to cheering your success.
The Federation of American Scientists (FAS) is a nonpartisan science and technology policy organization dedicated to bringing evidence-based expertise into government to help solve the country’s biggest challenges.
The Beeck Center for Social Impact + Innovation at Georgetown University is dedicated to improving how people experience government by strengthening the design and delivery of public services.
Research Agenda: Estimating the U.S. Government’s Return-on-Investment on Scientific Research & Development
The United States federal government invests nearly $150 billion annually in research and development. Four times ($937 billion in 2023, as estimated by NSF) this amount flows from state governments, private foundations, and corporate R&D budgets. These investments are made on the premise that they generate scientific, economic, and social returns. That premise is widely held. However, the supporting evidence generates wildly different estimates depending on the methods and available data.
That evidentiary weakness has always been a limitation. It is now, increasingly, a liability. Federal R&D budgets are subject to scrutiny of an intensity not seen in decades. Longstanding assumptions about the appropriate scale and direction of public investment in science are being actively contested across branches of government. In that environment, the inability to answer basic questions about what research investment produces – for whom, on what timeline, and compared to what alternative – leaves the field without the tools it needs to make its case. This agenda is designed, in part, to begin building those tools.
The literature on the returns to R&D investment has grown substantially over the past three decades. The work began in the 1950s with papers published by Zvi Griliches estimating the social rate of return to research activity. Economists have since estimated rates of return to federally funded basic research. Health economists have traced the pathway from NIH appropriations to pharmaceutical innovation to reductions in mortality. Innovation scholars have documented knowledge spillovers across firms, sectors, and national borders. This body of work has been useful, and has provided important empirical grounding for sustained public investment in science. But it has also left critical questions underexplored, and has not kept pace with the demands that policymakers, funders, and program administrators now place on evidence and evaluation.
Three gaps are especially consequential. First, the existing literature is concentrated on a narrow band of measurable outcomes – financial returns, patent counts, publication rates, and selected health outcomes – while the full range of value that R&D investment generates remains largely unmeasured. Social benefits, distributional effects, environmental outcomes, and the intrinsic value of scientific knowledge itself are acknowledged in principle but rarely captured in practice. The result is an evaluation vocabulary that systematically understates what investing in public research produces, and that is poorly suited to the constituencies who most need to understand it. Further, the paucity of data on the returns on investment in research makes it difficult to make informed decisions on future funding levels and allocations.
Second, the existing literature has made limited progress on the foundational problem of causal attribution. Demonstrating that an investment generated value is not the same as demonstrating that it generated value that would not otherwise have existed. The counterfactual question – what would have happened in the absence of a given funding decision – is rarely, if ever, answered with the rigor that credible evaluation requires. Where causal methods have been applied, they have typically addressed narrow, well-defined questions; broader claims about program or agency-level returns rest on methodological assumptions that are often implicit and rarely interrogated.
Third, the producers and consumers of evidence on the ROI of R&D are poorly connected. Federal agency program officers, congressional appropriators, budget examiners, state science advisors, philanthropic funders, and university research administrators all face versions of the same underlying questions – about returns, timescales, counterfactuals, spillovers, and accountability – but they ask those questions in different registers, with different data needs, on different timelines, and with different tolerances for methodological uncertainty. Research that is designed without these customers in mind and engaged in the process tends to reach only the audiences already most predisposed to engage with it. This means that key decision-makers are often making hard choices with little-to-no high-quality evidence on hand to support their thinking.
This research agenda is a response to those gaps. It was developed through a structured process of stakeholder engagement that surfaced both the range of outcomes that R&D investment is understood to produce and the specific informational needs of the actors responsible for making, evaluating, and defending funding decisions across the public, private, and philanthropic sectors. The result is a set of eleven research questions, organized from foundational to applied, that together constitute a program of inquiry capable of substantially advancing the field’s ability to measure, attribute, and communicate the returns to R&D investment.
The agenda does not promise that all of these questions can be fully answered. Several of the most important ones – including the construction of credible counterfactuals and the valuation of non-pecuniary returns – pose methodological challenges that current tools can address only partially. A transparent research agenda must acknowledge those limits clearly, both to set appropriate expectations and to direct methodological innovation toward the places where it is most needed. What the agenda does promise is that serious, well-designed inquiry into each of these questions would produce findings that are useful – to researchers, to practitioners, and to the policymakers who ultimately determine the scale and direction of public investment in science.
Methods
The primary vehicle for developing this set of research questions was a one-day workshop hosted in February 2026. The workshop convened academics, policymakers, and policy experts to discuss where the literature stands today and where it should head in the future. It was also intended to help launch a new initiative: the Pop-Up Journal. This initiative, whose first iteration will focus on the ROI of R&D (sometimes called the Griliches Question), will aim to answer many of the questions posed by participants and in this research agenda.
During the workshop, participants engaged in a series of exercises designed to elicit answers to two key questions:
- When we consider return-on-investment from R&D, what are the outcomes we should be measuring?
- What are the research questions that, if answered, are most likely to inform the decision-making of key stakeholders?
To answer the first question, we asked participants to identify a range of possible outcomes that might be important to someone trying to understand the return of their R&D investments.
To answer the second question, we assigned small groups different “personas” to consider – ranging from Congressional staff to federal agency leaders to universities and the private sector. They grappled with not just the types of research questions that are most novel, but the ones that were most likely to be useful to decision and policy makers.
To supplement the workshop, we also conducted a series of informal one-on-one interviews with experts – researchers who might one day seek to answer questions posed in this agenda, and policymakers who might use the evidence generated.
What We Recommend for Building Better Digital Service Teams, Initiatives, and Results
There is No Unifying Theory of Change
The book Good Strategy/Bad Strategy by Richard P. Rumelt states “Good strategy works by focusing energy and resources on one, or a very few, pivotal objectives whose accomplishment will lead to a cascade of favorable outcomes.”
In every retrospective we hosted, participants bemoaned the lack of a strategy and a longer-term theory of change in their work, or “how”, tied to outcomes. No shared strategy of work and functional purpose across the federal teams – USDS, 18F/TTS, OFCIO, and beyond – led to confusion, competition for limited resources, and a focus on individual team or organizational goals rather than shared agency- or government-wide outcomes. No shared strategy for mission outcomes at the government-wide or agency level meant we heard time and time again during the retros that teams at all levels of government felt like they were missing a chance at making an even greater, deeper impact. In the absence of such shared mission outcomes, digital service teams felt like their participation was the metric for success and their activity was a substitute for long-term progress. This is emblematic of a systemic problem – digital service initiatives operate within silos, compete for limited resources and talent, and often operate at agencies that lack a clear sense of how digital service initiatives contribute to their goals, ultimately diminishing the impact.
The lack of strategy impacted not just the teammates trying to do the work, it also impacted the agencies and stakeholders digital service teams interact with. A strategy defines a set of priorities that is repeatable and accountable, making it easier to partner, delegate, and work fast; it also communicates what you don’t want to work on, transparently outlining priorities. For digital service teams, strategy was absent but should exist at multiple levels. At the highest level, it articulates the theory for how digital services contribute to societal outcomes – how digital and service design improves public health through better access to benefits such as SNAP, or simplified access to healthcare. Strategy also exists at the government-wide level, defining priorities and processes for achieving those outcomes. And at the organizational and functional level, strategy defines the logic model for how diverse teams – including crisis response, modernization, implementation, product building, and operations and maintenance – work together across government.
And now, at a moment of significant technological change and demands on government, the stakes of having no strategy at each of these levels are higher than ever. Without a clear position on AI, government won’t even get their tactics right — they’ll spend all their time debating tools instead of outcomes. A strategy doesn’t require consensus. It is a signal of what you value, and provides the concrete steps to get what you’re trying to achieve, and why — so that people can ignore it, engage with it, challenge it, or build on it.
Moving forward, the digital service community should be a part of articulating an ambitious, outcomes based strategy at each level for what we want to achieve across the country in the next 5-10-20 years; and to look at defining foundational elements that make a strategy effective: building user-centered government and how to reform our institutions to become modern, responsive organizations.
User-centered government. Digital service practitioners have spent a decade hearing firsthand what people actually want and need from government. That knowledge shouldn’t stop at delivery- it should drive the strategy. Digital service teams are uniquely positioned to define those outcomes in concrete, user-centered terms and to hold the strategy accountable to them. No strategy should be set without that perspective at the table.
Institutional (re)design. For a decade, the civic tech community launched good services inside of – and sometimes in spite of – broken institutions. Direct File worked – and yet it didn’t change the IRS. That gap between modern ways of working and working across the organization to support radical change is the opportunity to update and upgrade our government. Digital leaders have the knowledge to go further: to define what a modern agency actually looks like, how it makes decisions, how it procures, how it hires.
Defining an ambitious strategy is an urgent first step: effective strategy is built on clear, user-centered outcomes and institutions that are structured to achieve them. Placing delivery technologists at the top of our organizations to shape both service delivery and how the institutions themselves run is one of the most critical things a political leader must do. The field is navigating AI adoption, budget austerity without a framework for prioritization, and planning for the future with a radically different federal landscape. An ambitious response to this moment is worth examining on its own and we look forward to contributing and seeing what our peers discover.
As is, the Digital Government Field Cannot Scale
Over the course of engaging 100+ individuals through the Digital Services Retros project, one theme that emerged was a shared concern that the individual contributions of any one team, no matter how talented, could not scale to influence how digital services were delivered throughout the rest of an agency. While teams of talented, experienced technical professionals could turn around quality products and evangelize a few allies to their style of working, ultimately teams struggled to turn their hard-won bright spots into scalable models of working across federal agencies.
The government digital services field’s current M.O. is to rely on a relatively small and scrappy pipeline of talent who attempt to sustain their work through oral histories and few resources or tools for which they’ve managed to win temporary exceptions. Scaling quality product development and service delivery across government demands a more mature approach, replacing unpredictable patterns of work with more cohesive processes, a shared vision of quality and strong resources that support the field of civic technology professionals.
Make it as easy to hire technologists as it is to hire lawyers
Current legislation and federal civil service code stops digital service teams from being able to hire the talent they want, build or buy the tools they need, and engage with users in the manner they need to. For this reason, the civic technology field has come to rely on a series of flexibilities and exceptions in lieu of real, streamlined repeatable career pathways.
Reliance on exceptional methods (e.g., term-based hiring, ad hoc programs that get designated salary exceptions) without reforming the system to enable a streamlined and quality process for hiring is an expedient approach, but not a sustainable or scalable one.
Policy leaders, including Congress, need to stop encouraging bandaids: digital service teams were never meant to be their perpetual excuse to avoid reform. Each needs to take concerted action to align the mechanics of the executive branch with modern hiring, workflows, and procurement that force every team to reinvent the wheel.
Make it someone’s job to scale change
Everything – from hiring, to ATO (authorization to operate) processes, to onboarding and everything in between – is a one-off, making lasting change within and across agencies near impossible. Moving forward, agencies and teams need to spend a percentage of time rewiring the agency as the work happens. Service delivery is a great opportunity to model new behaviors, work in an outcomes based manner, and use momentum to make change – this should become the norm and agencies should codify these upgrades alongside delivery work. The best way should be the default way, not the workaround. One strategy to target this need is to create a scale team – a team that shares best practice and is empowered, authorized, and expected to make sure the best ways become the default way. Institutions need to learn to expect change and implement better.
Additionally, there’s no shared definition of what good looks like in government digital delivery, which means digital teams in government are effectively grading their own homework. In contrast, within the private sector, there are industry standards for service-level agreements and user experience. These aren’t necessarily uniform across every enterprise or product, however there is broad alignment of what quality delivery reflects.
Government digital teams need to define their own “industry standards” for service levels and delivery. These definitions should not pigeonhole teams into rigid processes or unnecessary metrics, but rather provide a flexible benchmark that equips teams and leaders to gauge how successful their efforts are and how they compare across government and over time. In concrete terms, this could look like expectations for down time, user satisfaction indicators, and increased uptake of services among eligible populations. These also give agency leaders a way to set expectations and give users a basis for demanding better.
Expand field resources
Even as the field grows, there is still significant work to be done to develop its size and quality through shared vocabulary, resources, training, and methodologies. Organizations like Technologists for Public Good and events like the Code for America conference are promising valuable bright spots, but the potential for building a robust, well-connected field is far from saturated.
Establishing common training and methodologies would not only make the work itself more efficient, but would also create greater worker mobility across organizations. When practitioners share a common foundation, they become more interchangeable in the best sense; technologists are able to move between roles and institutions, which in turn drives more competitive opportunities and raises the quality of the field as a whole.
We Built Digital Teams, Not Services
“Build a digital service team” they said. And they did, oftentimes with great results, change, and service delivery. Over the last 10+ years, digital service teams have added capacity to struggling agencies across the country in order to deliver critical services that may otherwise not reach their intended user. This is a worthy goal. But what was the measurement of success? Was building the team the outcome?
During the Digital Services Retros project a pattern – across all levels of government (federal, state, local) – seemed to emerge: digital service teams were set up to add needed capacity to any number of solutions or as an outcome itself. The early strategy was – land the team, expand to solve new problems.
Somewhere along the way, the digital government field lost sight of what we were solving for. The unit of success was a digital service team; the thinking was that this team of talented individuals could be put against any set of problems or outcomes. And implicitly there was a correlation between the team being the intended outcome – an agency was deemed more “mature” or complete if it housed this team. To a certain degree this worked, and this worked well.
Today, most digital service teams have a similar set of attributes:
- A digital service is typically located centrally, either reporting into the principal or CIO/CTO or COO
- Power and authorities vary greatly; generally power is derived from political capital or occasional legislation that establishes it; they rarely have authorities to hire, fire, or hold teams accountable to outcomes
- The same set of skills were hired, regardless of the intended problem at hand, or outcome
It is assumed that digital services were somewhat plug and play – your handy government Swiss Army knife. Yet, the work itself varies greatly due to the priorities of leadership, the work it is empowered to do, and the depth at which it is allowed to operate. These teams have had great impact – and also, it is time to examine other models, units, and ways of working that can complement the standard digital service team.
The needs are so disparate and each context they work in so unique, we need a wider set of models from which to draw upon on purpose, not happenstance. Agencies and leaders at all levels need to have the right model that fits their constituents’ or agency’s or legislative need, as well as their agency’s maturity.
In its current evolutionary phase, most digital service teams are stand-alone teams assigned to deliver a specific task, often embedded in the CIO or agency head’s office. It is true that top cover and leadership capital is critical for success; however, we would like to challenge this new model in an attempt to create more enduring, transformative change for end users and for agencies.
The key ingredient: organizing the work around the shared outcome of a service, rather than a functional or organizational boundary. This orientation focuses the team on the outcome and be held accountable to its delivery. Such teams are more likely to be enduring, as the services that they deliver are either embedded in statute or have a permanency. Furthermore, the funding is allocated to outcomes that are aligned to the strategic goals (and budget) of the organization, leading to more enduring change.
The Service Team
The target state: a service. Established by the UK’s Government Digital Service and developed further by practitioners like Kate Tarling, a service team is organized around a service as experienced by an external user, i.e. “file my taxes,” “apply for college financial aid,” “enroll in benefits.” It’s not a project, nor an app, nor a vendor run system – a service is a thing a person needs to do.
A service, as Tarling defines it is described from the user’s point of view; encompasses every step between the user and the outcome; crosses organizational silos; and ties directly to the institution’s goals. This is similar to the “product operating model” seen in the private sector.
Where government services depart from a typical product team are the unique constraints faced by the public sector. A private sector product team is usually a mix of engineers, designers, and a product manager sitting in a product silo. A government service team needs that, plus program and policy staff, and often lawyers who have to navigate the policy requirements alongside the technical ones. Crucially, the user of government services also usually can’t “opt out” for a competitor product; if a benefits application breaks, the user has no other option.
These differences in the staffing and user experience are significant, however the underlying logic of a persistent, empowered ownership team remains the same. The product operating model gives government the operating mechanics: how a team should be funded, staffed, and run day to day. The service model outlines the unit that the team should be organized around: the user’s full journey, rather than an IT system, or office, or budget line. Government needs both the discipline of the product operating model, applied to the full weight of what an end-to-end government service actually requires.
A few items stand out here. First, a service is an end-to-end journey. In most agencies a service team by this definition would span across multiple teams and silos in an organization. A service also completes the user’s task (and it does so confidently, securely, and accurately). And a service team crosses organizational boundaries and is fully empowered to deliver this complete, end-to-end task. Restructuring delivery around an end-to-end service, either collapsing or working across silos, allows digital to truly shape the work that matters most to users.
That last part is what makes this model sticky. A service team organized around “Renew My Passport” is less likely to be disbanded when leadership turns over, because the service doesn’t go away. Funding is allocated to an outcome, year after year. The work survives because it’s embedded in something tangible.
We don’t have to look to the UK for proof of concept. An independent assessment of the IRS conducted in 2024 described Direct File as already ‘functionally operating as an isolated service-oriented organization.’ The model worked well and was proving itself across the organization for two prominent reasons. First, the most important decision the Direct File team made was to appoint a single accountable owner empowered to make day-to-day decisions. This leadership and governance model allowed the team to work in an empowered manner, at pace. Second, the service team joined up customer support and product teams.
What we heard in the retros was the flip side of that: projects that stalled because of indecision, too many stakeholders, being dropped into ambiguous situations without clear ownership, among other reasons. Building end-to-end service teams is not for the faint of heart – achieving this model of embedded technical and program teams, working collaboratively on an end-to-end journey, fully empowered to update processes and ways of working as they go is the mature end of the digital government spectrum. But it is included here as it not only achieves better results for the end user, it also helps the agency and staff transform as they work in a new, fully digital, collaborative manner.
Different Models for Different Problems
Not every new challenge in government requires the same organizational response. During our retros, participants bemoaned how USDS and 18F didn’t often build the right team for the problem they were trying to solve. This was often due to multiple reasons, top among them scarcity of talent. Below are models and purposes that emerged from our retros, each with distinct purposes, skill requirements, and conditions for success. These aren’t mutually exclusive; a mature digital organization will likely need more than one at once. The service team is the north star, the most mature model. The others are legitimate and necessary, but they should be chosen deliberately and not defaulted into.
Additional models for teams that could be applied to different problems, include:
A Forward Looking Agenda for Digital Service Delivery
This is the moment for ambitious change. The digital government field has an opportunity to build a more responsive and resilient government by pushing into expanded frontiers, with new tools, approaches, and even organizations that don’t exist yet. While the pace of change can be overwhelming, there is something clarifying about a moment when people are questioning the value of institutions themselves. This is the time for radical experimentation, delivery, and exploration.
So what’s next? The recommendations we’ve laid out – building a coherent strategy, matching the right team for the right problem, and scaling what works to stabilize and reposition the field can be read through multiple future-looking lenses. First institutional: what does building ambitious and capable government institutions look like, and how do you build it? Another is contextual:, trends like artificial intelligence and austerity are both going to reshape what’s possible and not in directions we can easily predict.
The following options and ideas exist on a spectrum, and are part of a suite of reform ideas that can help build government with the ambition and capacity to deliver. We welcome challenge, debate, and more ideas to this dialogue – love or hate it? Great! Tell us! Like an idea? Great! Steal it and go deeper!
Federal Digital Service Delivery
Building ambitious and capable government institutions – Federal edition
Federal capacity, or “The Department of Digital”
Federal digital and delivery capacity will continue to be a necessary piece of a strong, delivery oriented government. The question is – now that the US Digital Service has become DOGE and 18F is dismantled, what should the future model be?
The federal government needs a strong, centralized digital capacity responsible for three distinct purposes: capacity to deliver on presidential priorities, setting standards for better delivery, and building and managing shared platforms that can be used across government to save both government and external users time and money. For inspiration on what this centralized structure could be in a federal system, we look to Germany and the UK.
Germany’s recently established Ministry for Digital Transformation and Government Modernisation is delivering a portfolio of services, holding agencies across the government accountable for excellent, modern services, and ensuring that all software that is developed is interoperable across agencies and to devolved jurisdictions. It is a priority of the German government to build software that can be reused not just across the central government, but to states as well. Embedded in the ministry is a 250+ strong digital service team, responsible for excellent user experiences and digitizing the key interactions with government.
Germany is also taking the software it uses seriously and, in an effort to ensure national sovereignty over their own technology, is setting out to build their own full stack office software, across document management, presentations, collaboration suites, and other essential office software for use by civil servants across the country. It has become a national priority to not get locked into any single vendor or be reliant on any single country to provide software or cloud services; building resiliency across the tech stack is a strategic national necessity, not an afterthought.
The UK’s Government Digital Service (GDS) established a central team that builds platforms that can be used across government and sets standards that all new services must meet before they launch. These standards ensure consistent design and interaction patterns, end-to-end transaction completion, and more. The central team also builds shared platforms – GOV.UK Login, Pay, Notify, NDX Cloud, and Design System. More recently, they began developing shared open source frameworks to support local governments across the country. These platforms have become an essential foundational layer for the modernization of the UK’s government; the central team has many tools and templates that are easy to use, replicate, and apply to launching new services.
In the U.S., a central digital department could truly hold agencies accountable and help drive the momentum for change across the federal government, as well as support, build, and launch critical government platforms. Additionally, identifying and setting shared standards that not only establish a baseline for experiences, but also come with muscular authorities to enforce and hold teams accountable to those standards. What does accountability look like in practice? Agencies having their services assessed and getting approval before launching a new service experience, as the UK does now.
Recommended additions to the U.S. toolkit
Example standards. Standards that define what good looks like and come with the authority to enforce it could include:
- AI in practice – guidance for application and usage
- Service standards – design, interaction, call center, and service completion standards
- Budget controls – oversight over digital and tech procurements
- Service performance standards – transparency into service performance across government
Example platforms. Platforms any agency or jurisdiction can plug into, rather than procuring their own version from scratch. These could include:
- Login.gov
- A payment platform
- Income verification platform
- AI LLMs for civil servants that are compliant with federal and state laws (for example, Berlin’s BarGPT for Berlin city government employees and is GDPR compliant)
- Open Source office software (for example, France’s Lasuite) and code (for example, U.S. Web Design System (USWDS))
- Identifying projects similar in nature and scope to Ukraine’s Diia
Federal agencies – models for services and more
At the agency level, there are multiple models to support service delivery and leaders should support the model that meets their needs. However, almost universally we recommend that agencies should explore the service model for their key services. This model organizes teams and the work around the shared outcome of a service, rather than a functional or organizational boundary. Working across silos, in multidisciplinary teams leads to better outcomes for users and helps transform the organization into a more modern, responsive one along the way.
State and Local Digital Service Delivery
Building ambitious and capable government institutions: Working across federal and state/local
Federalism, what is it good for?
Federalism is great for ensuring power doesn’t get too centralized when managing a huge and hugely diverse country. However, federalism is rarely good for the end-user experience or for delivery efficiency. A review found that federal legislation meant to quickly build infrastructure, support cities and states during COVID, and pave a path towards a greener country was slow to get out the door and make tangible. The matrixed delivery of federal -> state -> city/local doesn’t always support efficient implementation, and it also doesn’t have to be this complicated.
An ambitious federal digital strategy should include consideration of the complete delivery cycle – inclusive of legislation, the disbursement of funds, tracking all the way down to the front line and ultimately the intended end users. There are two potential areas to explore for better outcomes – a ‘middle layer’ of shared open, public infrastructure that helps budget-strapped state/local governments deliver on key services and the inclusion of state/local digital capacity to support implementation of any legislation that requires a user experience.
A menu of tools: open source platforms, shared infrastructure, and public options
There are countless examples of large IT vendors building the same product, poorly, for 50 states. This model can and should be reimagined – moving towards a vision where governments can opt-in to a shared public infrastructure. It is time to look at options that tie federal outcomes to delivery intent: We need shared public infrastructure around key legislation and universal platforms. These could support both internal government efficiency and end-user experience.
Shared open source platforms and digital infrastructure can provide government teams across the country with additional options for delivery at a national scale. This ‘middle layer’ would look at services that are required in multiple jurisdictions or infrastructure necessary to implement new legislation. Such platforms could exist as a public option – government-provided services that coexist with one or more private options.
Governments shouldn’t have to build from scratch: Modern income verification infrastructure really only needs to be built once and made available to jurisdictions that opt-in and could be used in a countless number of ways, from federal scholarship applications to SNAP. Governments at all levels lose money to payment processing fees. A public option payment platform would cut costs and add a new competitor to the market, saving taxpayers money. Universal moments, such as birth and death registry, could be built centrally and deployed locally. Even when state and local governments build their own services, government registries and digital services could be built using a government-managed open-source low-code platform, like is being done in Ukraine with Diia.Engine.
To date, these delivery challenges have been too onerous to tackle. States are often reluctant to share data and platforms. Some jurisdictions have begun planning shared procurement strategies, but radically different, outcomes-based delivery will take reimagined governance and significant political will.
State and Local delivery capacity
State and city governments are the source of many peoples’ daily experiences with public services and infrastructure. Yet most lack the resources and capacity needed to deliver the efficient, seamless, and intuitive digital experience that the public has come to expect in the private sector. This gap is not a reflection of ambition or effort at the state level, but the result of long-standing structural constraints on funding, talent, and technical support.
Existing federal funding mechanisms and technical assistance programs are insufficient to close this gap. While federal dollars often support state IT projects, they rarely come with embedded technical capacity, hands-on delivery support, or durable mechanisms for knowledge transfer. Today, states face persistent challenges recruiting and retaining digital talent due to rigid hiring systems, compensation constraints, and limited professional development pathways.
From this, we propose a couple of options to close the capacity experience gap between the end user and state and local institutions.
- Include implementation or service teams as part of legislation to ensure that delivery intent is actually possible and is critical to the success of any legislation. Building that capacity in-house, in the institution that is responsible for the end-user interaction, is a critical step towards a successful implementation.
- Centrally funded technical assistance – in this model, a dedicated central office in the federal government – should be established to provide consultative and technical assistance to state governments at scale. This office would form interdisciplinary teams that consist of state government employees and technologists who work on high impact issues of service delivery, ranging from social safety net access, to environmental permitting, to shared digital infrastructure modernization.
Artificial Intelligence Risks and Rewards in Digital Service Delivery
AI was not a major topic during the retros, largely because many practitioners view AI as one of many commercially available technologies that can be deployed to solve problems. However, interest in AI is growing as governments increasingly experiment with and deploy AI in their operations and service delivery.
AI, when deployed responsibly and with a clear purpose in mind, has the potential to assist in streamlining benefits, reaching citizens with timely information, and automating certain tasks. However, AI does not exist in a social, economic, or political vacuum and carries significant risk to governments and the general public through cybersecurity vulnerabilities, data privacy risks, entrenched bias, intellectual property infringement, and more. These risks highlight the need for a well informed government workforce, and additional in-house technical experts within government to support users and make decisions that advance progress with a robust understanding of the implications.
Artificial Intelligence in the age of austerity
During periods of financial uncertainty or recessions it can be challenging to make the case for AI adoption when it weighs against more urgent needs. Additionally, nationwide, states, counties, and cities are facing tighter budgets due to existing deficits and a change in federal funding. Resource- and capacity-constrained institutions are turning to AI to help fill that gap and deliver for their constituents. But to ensure that AI adoption is fair and transparent, governments need AI strategies and strong, technical talent embedded to deliver on this new technology.
This moment demands confronting a reality that is complex, rapidly evolving, and where just about every decision will have a profound impact on the lives of those the government is meant to serve and the institutions themselves. If the government and the civic tech community are not intentional about how we design, procure, use, and govern this new technology, it has the risk of making capacity issues worse and undermining trust in institutions that are already fragile.
Artificial Intelligence, practically
In this moment, our recommendations – have a strategy tied to outcomes, build embedded multidisciplinary teams, make it easy to build and sustain this capacity – are more important than ever, as AI becomes a critical tool that governments across the country are rapidly adopting. AI can help improve service delivery when applied to specific problem-driven use cases and deployed in ways that promote fair, user-centric, and transparent application.
Where we would deploy AI towards service delivery:
- Embedding in the practices of front line employees, to understand where processes can be automated, notes transcribed, and the right approach to using LLMs that allow employees to save time on notes, searching and applying different policies, etc, ultimately allowing them to spend more time with clients.
- Prototyping new experiences, forms, and interactions – normally these are interactions that require lengthy procurement processes, now governments have the opportunity to use new AI tools to perform exploratory work.
- Other problem-driven uses that focus on solving specific challenges rather than adopting technology for its own sake.
- With content support across translation, transcription, simplification.
Principles:
- Build with, not for – build systems that complement the lived experience of the government employee and meaningfully include end-users in the design and testing of AI platforms.
- Be transparent around how and when AI is used, especially in decisionmaking processes or in the provision of benefits.
- Best practices include: public use-case inventories, and consumer notification/disclosure of AI use (and where)
- De-bias, wherever possible – Understand how LLMs have certain biases and how, as government employees, there are frameworks around those biases to mitigate potential risk or harm.
- Being aware of existing applicable laws, and of increased compliance risk with AI tools that have limited interpretability or control over data inputs (such as adverse action notices that are required under FCRA/ECOA)
- Pre-deployment planning: Before you deploy, understanding how it is best used, and situations in which in can actually make things work less well (i.e., when you need factual information)
- Preventing buyers remorse: Clear procurement guardrails that include sunset provisions, and auditability/interpretability (to prevent accidental bias).
- California is a great example. The state piloted multiple programs to improve service delivery and killed the ones that didn’t work or were too costly.
- Preventing buyers remorse: Clear procurement guardrails that include sunset provisions, and auditability/interpretability (to prevent accidental bias).
- Consistent quality control: As agencies independently acquire a growing number of services, maintaining consistent quality control and oversight becomes increasingly difficult. A centralized review and governance function should evaluate and monitor the tools and services being adopted across agencies. (i.e., a FEDRAMP process for AI)
- Centralized vetting of AI models and products ensures consistent standards and is more effective than fragmented (and often more expensive) agency-level procurement.
The platforms and models that we choose matter. Again, there is inspiration to be found abroad. The Swiss Euria GPT is fully powered by renewable energy, and all heat produced by the platform’s data centers is fed back into Geneva’s heating network; furthermore, it does not collect or train its models from any user data and is fully compliant with Swiss data and privacy laws.
While the future holds seemingly unlimited uncertainty, there is a lot of opportunity to learn from what’s come before and to radically redesign the future of digital government.
This Proposed Rule Could Change American Science Forever. We Read It So You Don’t Have To.
On May 29, the Office of Management and Budget (OMB) dropped a 108 page (single-spaced) proposed rule to “revise the Guidance for Federal Financial Assistance to improve government-wide policies and requirements related to the management of grants, cooperative agreements, and other forms of assistance.” If you are not a dyed-in-the-wool wonk, here’s a translation: this proposed rule would change the way the federal government funds scientific research. And state energy programs. And community health grants. And the local governments trying to modernize how they deliver services. Like a lot.
Aside: there is something wrong with the way we fund science in this country — the list of flaws is long and we have to own them. We also have to build something durable, not treat our principles like a suicide pact.
Rule changes like this thrive in tall weeds: the language is arcane, esoteric even, meant to be understood by lawyers and policy experts. Here’s what’s actually in them.
How we got here
There is a crisis of trust in science. Trust in science is still lower than before the COVID-19 pandemic reshaped our reality, with trust in federal science lower still. This trust is also partisan: Democrats are more likely to have confidence in scientists than Republicans are. Many people struggle to trust scientific processes and activities, to have faith in government as an interpreter of scientific findings, to feel public science priorities represent their needs. The federal research funding apparatus feels distant from most people’s lives, and the connection between public investment and public benefit isn’t easily traceable by the people whose taxes make it happen.
The federal execution of science has real problems too. Administrative burden, convoluted workflows, a funding system that concentrates awards among the already-large and already-connected, a merit review process that has calcified in ways that make it slow and risk-averse. As a community we have to own that. The fish psilocybin study wasn’t taxpayer-funded, but some real head-scratchers were (for the record: some of them were worth it).
Backstopping all of this is a weakening of Congress’s role in R&D. While there is bipartisan support for research in Congress (like the many Democratic and Republican lawmakers who have championed investment across AI regulation, wildland fire, and on emerging technologies like biotech and quantum computing), Congress has been relegated to a rump when it comes to their fiduciary duty to scientific research. Money expressly authorized and appropriated by the people’s house is being held up, research agencies are being starved of their necessary funds, and there is hardly anyone left to do the work.
In that context, the Trump administration has been establishing a policy lineage for major change in how the federal government invests in many areas, including R&D. The 2025 Restoring Gold Standard Science executive order directed political appointees to oversee agency scientific decisions and resolve GSS “violations,” inserting politics into processes where existing scientific integrity policies had specifically been designed to keep it out. Agency implementation plans followed across multiple science agencies. This proposed rule is the next step.
Back to these rules
How much have you heard the phrase “gold standard science” in the last year? As a concept, it was reaching for something important: accountability in how research dollars get spent, scrutiny of whether peer review had become a closed loop, a question about whether federally funded science was delivering for the public that funds it. What it became in practice is something different.
Is it, for example, the systemic weakening of career staff at science agencies to replace their blood-sweat-and-tears expertise with political appointees? Is it firing the National Science Board en masse over email on a weekend? Is it gagging the NSF watchdog meant to uncover research misconduct and fraud? This doesn’t begin to cover the politicking that has diminished our national public health apparatus, or the bed bugs in the Animal and Plant Inspection Service building.
What gold standard science became in practice is a mechanism for political appointees to override scientific judgment and frame ideological interference as methodological rigor. This proposed rule puts that mechanism into binding regulation, government-wide: mandatory political review of every discretionary grant before it’s awarded, expanded authority to terminate awards mid-stream, new restrictions on what funded researchers can publish, say, or collaborate on internationally.
Science is not the only thing at stake. The federal grants system funds an enormous range of what government actually does: states building out energy infrastructure, local health departments running maternal care programs, nonprofits delivering workforce services, cities trying to modernize how they serve residents. OMB’s proposed rule governs all of it: billions in federal grants, every dollar now subject to the same appointee review and presidential priority test. A political appointee gets to decide, mid-stream, that the work no longer matters. That’s not a grants system anyone can build anything ambitious in.
Replacing expert peer review with political appointees doesn’t make federal financial assistance of any kind more accountable to the public, it makes it accountable to whichever political team won the last election and their appointees’ desire to micromanage. Every grantee in America is now operating on that assumption.
The proposed change to §200.205 would formalize prior guidance for senior appointees – not career scientists, not program officers, not people who know how to do this thing – to review every discretionary grant before it’s awarded (science and beyond).
For science specifically, it goes further: appointees expressly prohibited from deferring to peer review [read: experts] on the matter. Since WWII nearly every science agency has emphasized independent expert peer review as THE measure of scientific merit. Even your 8th grade science teacher emphasized this. Under the change to §200.205(d), a political appointee can override the scientific community’s judgment just because. Discretionary awards must also “advance the President’s policy priorities” – not national security, or public health, nor foundational science priorities. Presidential ones.
Under current rules, terminating a grant requires a finding of noncompliance or fraud, which is a high bar because multi-year awards require multi-year commitments. You can’t build a cutting edge research program or radically transform a grid on a one-year horizon. The proposed change to §200.340(a)(2) drops that bar entirely. No finding required; termination is available whenever an award no longer aligns with agency priorities or the national interest. Yes that could mean almost anything. There are currently 150,000 active multi-year awards operating under the assumption that finishing what they started is possible. The chilling effect on applications may be as significant as the terminations themselves: why spend months on a competitive grant application, or structure your organization around a multi-year award, if the whole thing can evaporate at will?
Then there’s the elimination of fixed-amount awards. Smaller organizations, the ones without teams of grants managers and compliance lawyers, depend on fixed-amount awards because they’re manageable. Kill them and you’ve told a significant chunk of the grants ecosystem that they’re no longer in the running.
Proposed changes to §200.421, §200.432, and §200.461 restrict the use of federal funds for publications, press communications, and conference attendance. For researchers, this directly conflicts with a longstanding OSTP mandate requiring federally funded research to be published open-access. You can’t comply with one federal requirement without violating another. But the restrictions aren’t limited to science: any federally funded practitioner sharing findings, any state agency presenting at a national conference, any nonprofit documenting what their grant actually accomplished runs into the same wall. In other words: you can’t do public work that the public can see and learn about.
The proposed changes to §200.220 and§200.202(e) would require case-by-case approval for international research collaborations — a domestic-first framework that treats standard scientific practice as a special exception. (We did just bring a Canadian to the moon with us, for the record.) International cooperation is standard practice across many scientific disciplines; fruitful, peaceful scientific collaboration has been the norm with any number of countries (that we are already engaged in multilateral collaboration with)? A domestic-first framework that requires case-by-case approval would be detrimental to international public health efforts, where foreign scientists are leading research into treatments and containment.
Changes to §200.206 look a lot like a loyalty test and not just for science. Any organization applying for a federal grant would be subject to eligibility review based on its affiliations, activities, and perceived alignment with administration priorities. Congress tried this one in 1949 when they tried to sneak in a loyalty test affidavit into the National Science Foundation Bill. We said it in 1949 and we’ll say it again: “Its sole justification for inclusion is concession to current fears and hysteria. Totally ineffective in detecting actual enemies of the U.S., it is significant only in its indication of the state of mind of the country – one of unreasoning insecurity and fear. To fail to oppose the provision is to accept this state of mind and permit it to go on to even more dangerous manifestations.”
The provision that should worry everyone is in §200.202(a)(iii): a requirement that federal programs “align with administration policies and priorities.” Science funding has always been political and anyone telling you otherwise is selling something. Democratic legitimacy matters for public investment, and the federal government should be accountable to the people whose taxes fund it. But there’s a meaningful difference between federal priorities and administration priorities that this rule deliberately erases. The federal government is a massive institution with a general mandate to serve the public across generations. An administration comes and goes every four to eight years, with narrower ideological agendas and a much shorter time horizon. Requiring every grant dollar to align with the current administration’s priorities isn’t accountability, it’s a different thing entirely.
Two things can be true
To be fair, a few things in this rule are worth having. NOFO streamlining and encouragement of multi-year awards are real improvements to a pre-award process that has frustrated applicants for years. The rule also comes down hard on merit review as a source of stagnation, and to an extent that’s not wrong. We’ll take those. (Further FAS insights into merit review are forthcoming, but traditionalists be forewarned: we make a many-pronged call for reform.) As a scientific community we have to own the current flaws. We also have to build something durable, not treat them like a suicide pact.
Step back from the individual provisions and the systemic problem becomes clear: this rule is a demand signal and institutions will respond to it rationally. Universities, nonprofits, state agencies, and local governments will look at these conditions — arbitrary termination authority, political pre-clearance, loyalty reviews — and make reasonable decisions about what’s worth pursuing. You cannot have loyalty tests and a scientific effort the size of the Manhattan Project or in new areas of discovery where the trajectory is unknown. Smaller institutions without the legal and administrative capacity to manage the new compliance burden will exit the market; larger ones will self-censor. The portfolio of federally funded work will get narrower because the risk calculus changed.
There’s an irony here for anyone who believes in competent government: a system that can override expert judgment at will has less use for experts. That’s a demand signal too. There is a world beyond merit review emerging, like the NSF X-Labs initiative, team science models, Tech Labs built on baked-in independence. Exciting constructions, none of them ready for prime time. We can’t throw the baby out with the bathwater. Better results from federal grants are a legitimate goal, and the path there isn’t complicated to describe: grants systems that actually reflect the communities and problems they’re meant to serve, and that are designed to learn from what happens after the money goes out the door. We don’t have that now and this proposed rule doesn’t get there either.
So what’s next
Many of our peers are outraged. AAAS CEO Sudip Parikh calls these proposed changes “a brazen power grab,” while Irene Ngun, Assistant Director of Policy and Advocacy at Stand Up For Science, plainly calls it a “weaponization.” Across the science and technology policy community, there is a feeling that this represents the final bell toll of an apocalyptic-level event for American science. Whether or not that is your read on the situation, this is as significant as a change as can be. Independence is the source of scientific integrity. (And those outside of this community should care too: OMB’s proposal would govern billions in federal grants. Every dollar everywhere will be subject to the same appointee review and need to meet presidential priorities.)
There is no question this is a Big Deal. If you are a university or research lab, or aspire to work in one, or are simply an enthusiast of federally-funded research (the kind that gave us the internet!), what’s next will matter. It is likely these changes will lead to litigation. When that time comes, we will offer dispassionate analysis, giving primacy to facts and figures. But before that, we are exploring every avenue available to us to revert this threat.
- We’re in constant contact with science advocacy groups, industry, scientists and innovators, and policymakers to stay on top of the latest dynamics and opportunities for action.
- We’re reaching out to congress and the executive branch with substantive oversight priorities. We need members from both sides of the aisle to act on these. Raise your hand if this is you. Some of these include:
- Conflicting mandates between this rule and other rules throughout government (like the Office of Science and Technology Policy’s open access publishing guidance),
- Clarification about how this rule affects existing and multi-year awards, and
- A Government Accountability Office study request.
- We’re preparing a public comment and encourage you and your institution to do the same.
What the Metascience Community Should Learn From the Federal Evidence Movement Before Making Our Mistakes
There is a growing community of people inside and around the federal government who believe we should apply the scientific method to science itself: how grants are awarded, how peer review works, how labs are organized, how R&D portfolios are built. In some circles this is called metascience, others it goes by science of science, or research on research. The label matters less than the conviction that how we fund and structure science isn’t fixed and that we could be doing it a lot better.
The political moment may be unusually open to acting on this conviction, as R&D institutions face pressures and disruptions not seen since the post-World War II era.
A quick orientation on where things stand: most metascience activity today is external researchers studying government R&D programs from the outside, and that community is growing. Inside the government, interest is picking up: a handful of agencies are starting to think seriously about what internal capacity might look like, with NSF’s proposed metascience unit in the FY2027 budget request as the most visible signal so far. Whether that momentum builds into something more structured, or stays scattered or administration-dependent, remains to be seen.
There’s no Evidence Act equivalent being seriously discussed, but it’s a great moment for laying the ingredients for what comes next. This piece is aimed at both audiences: researchers trying to make their work matter inside agencies, and the agency leaders and staff thinking about standing something up.
I want to be a serious champion for building this capacity inside the government. But I also want to make sure we don’t sleepwalk into a set of traps that I watched swallow another reform movement — one I was part of! — over the last decade. The federal evidence community, which grew dramatically following the Foundations for Evidence-Based Policymaking Act of 2018, had serious ambitions and major accomplishments. It also made structural mistakes that a metascience community could easily repeat. Here’s my take on how we can learn from each other (and what you should steal).
Design around decisions people need (or want) to make, not just questions the research community finds interesting, and be useful early.
Know the decision calendar; a finding that arrives late doesn’t exist.
Co-design with program officers; make their success your success.
Existence of evidence doesn’t equal use; figure out what motivates the people who need to act.
Government needs in-house flexibility to do the work.
Decide whether this is a destination or a waystation and build accordingly.
Solve the structural problems first.
External accountability, cross-agency champions, and Congressional relationships are survival infrastructure.
Episodic engagement is a design failure.
What the evidence community got right (somewhat-evidence-based answer: quite a bit!)
The Evidence Act was a major achievement both as legislation and systems change that continues to make stronger policy possible. It normalized the idea that the government can admit knowledge gaps and curiosity. That agencies should be asking hard questions about whether their programs work, and that building the infrastructure to answer them is important (to me, this is a fundamental of democratic governance, something we owe the American people to maintain legitimacy). Asking “does this program actually do what we think it does?” could read as hostile or politically threatening. The Evidence Act made it standard management practice and that cultural shift, however incomplete, was not nothing!
The infrastructure that followed (Learning Agendas, Evaluation Officers, CDO Councils, OMB evaluation guidance) created shared vocabulary and accountability that hadn’t existed before. In the agencies where it took hold, it opened space for questions, roles, partnerships, and curiosity that previously had no institutional home. Giving someone a title that made clear their role was to facilitate knowledge generation and translation in a bureaucracy that knows how to build on structural opportunity is a big step. Setting a standard process to collect questions needed for effective governance is huge, culturally and administratively.
External accountability mattered too. OMB guidance, GAO oversight, and congressional interest created pressure that internal motivation alone couldn’t sustain. Compliance requirements work when someone is going to ask about them and care about the response (spoiler: I had to do this a lot, and occasionally explain the difference between, say, audits and evaluations). Where the evidence work shaped decisions, it was usually because someone with budget authority and leadership access wanted it. And because a community of practice built enough shared norms to carry the work across agencies and administrations.
What went wrong (or not as well as it should have) and why metascience can learn from our experiments
Insert here tremendous respect and awe for the evaluation officers and their colleagues who fought the hard fight without the support they should have had.
We built supply without equal attention to demand. Evaluation planning and learning agendas were sometimes produced because Congress and OMB required them, not just because program offices were always asking for answers. Carol Weiss has called this the “two communities” problem for ages: researchers and policymakers operating in parallel universes with different timelines, incentives, and languages. And while the community has iterated in that moniker and concept for a long time, we’ve never quite solved it. Too often the results landed in reports nobody read (if they were published at all!), or in inboxes where they became someone else’s problem, or on a timeline that didn’t match decisionmaking. The basic customer question — who needs this, and when, and in what form — wasn’t asked enough, and when it was, we didn’t have great leverage to change.
We got divorced from the workflow. Evaluations routinely finished after the budget cycles and policy windows they were meant to inform. The evidence community struggled to map its work to actual decision points: appropriations timelines, leadership transitions, program reauthorizations. While the evidence community would be well served by considering a range of flexible and timely evidence models, gold-standard evidence methods like Randomized Controlled Trials of major programs can and do take time (certainly more time than a single fiscal year). Unsurprisingly, format mattered too: the people who needed to act, needed a two-pager, or, better, a conversation; more than a technical report delivered six months after the window had closed.
We (cringe) made ourselves hard to work with. The evidence community was often expert-centric rather than partner-centric, more focused on what constituted the highest quality legitimate evidence than on what would be useful, approachable, or on what timeline (see Jen Pahlka’s thinking on “stop energy” vs. “go energy”). The vocabulary was sometimes alienating and methodological gatekeeping was a real downer. More structurally, evaluation offices were sometimes poorly located organizationally, sitting outside program design and budget processes where leverage lived, and relationships upstream or downstream didn’t always come naturally.
We had a LOT of questions but buried them where no one could find them. On the other side of the equation, we too often made a reasonably good effort at compiling our research and evaluation questions in Learning Agendas and did the government equivalent of post and pray, launching a PDF deep on a federal website without requisite effort to connect it it to researchers who would’ve loved to follow up. There were great exceptions: outside the government, I participated in a “matchmaking” session on the President’s Management Agenda Learning agenda, connecting federal leaders with research teams excited to engage on their challenges. The OMB evidence lead I was privileged to work with created a Learning Agenda Questions Dashboard (on evaluation.gov, RIP), and the “evidence project portal” to consolidate opportunities for outside researchers.
We lost the hiring, funding, and buying battles. The Evidence Act directed OPM to develop a hiring classification to support building out the evaluation community. As the person at OMB responsible for pushing that effort (years after the deadline), I watched OPM’s underresourced and sometimes calcified approach to classification make this so challenging that colleagues described it as the worst professional experience of their careers. As an ongoing consequence, agencies defaulted to using generic job series for evidence functions that couldn’t elevate qualified people. Evaluation officers are frequently double and triple-hatted as performance managers, data scientists, and learning officers, often with no dedicated staff, no protected budget, and no solid career path. Likewise, the paths to funding research were highly varied and full of dragons. I could not in good faith consistently tell an agency “here’s how to get your high priority research funded” because it was so variable across agencies. Likewise, unwieldy procurement vehicles added unnecessary burden to a process that already struggled to get RFPs out the door.
We struggled with the theory of adoption. The simplistic foundational assumption was: create the requirement, do the study, policymakers use it; policymakers create a program, evidence is generated, change is made. It SOUNDS right but in practice so much was wrong in that chain because it didn’t consider incentives and timelines. Who needs this finding the most, and when? What would motivate them to change their behavior? What’s standing in their way? Am I asking a question they can act on? Even when the evidence was good, the pathway from finding to decision was assumed rather than designed.
We kept building administrative burden while assuming people wanted it. Learning Agendas and Annual Evaluation Plans and Policies are great concepts and valuable ways to bring learning and policy communities together. But even in the best of worlds these were still compliance requirements layered on top of staff who were already stretched, and in the worst, when done badly, they overcomplicated what should have been a culture changing moment. A metascience function that responds to that history by adding more reporting requirements would be its own kind of failure. The goal should be fewer dragons and headaches on on the path from question to useful answer.
And we struggled with politics. The truth is that many policy leaders don’t want to know if their idea won’t work or didn’t work. Publishing work that shows waste to taxpayers is politically costly, and that problem doesn’t disappear because a law requires evaluation plans. Likewise, sometimes programs do work well and the evidence shows it brilliantly, but politics means that success is less desirable to advertise.
But failures weren’t all inside the government. The academic communities best positioned to do rigorous, policy-relevant evaluation work faced their own incentive problems. Publishing in top journals rewards novelty, methodological elegance, and positive findings (even if you have to p-hack your way there); relevance to a policymaker’s actual questions is less important. The researcher who produces a technically brilliant study and never engages with the agency whose program they studied is likely more fully rewarded by their institution than those supporting policy design. Fortunately, there are researchers across disciplines who care about public impact, and there are organizations like the Evidence-to-Impact Collaborative at Penn State doing serious work to build the infrastructure that makes researcher-policymaker relationships function. But consistently orienting the research community toward the questions that matter inside agencies is a question metascience will inherit too.
Hark! There is a Fork in the Road!
The emerging federal metascience community is asking fascinating questions that are equally vital for democratic legitimacy: beyond “did this program work” to “how does the federal R&D enterprise itself work, and how could it work better?”
But it faces the same fork in the road and even more disruptive moment. The metascience community is also trying to do this work in a volatile moment, where the institutions being studied are changing fast, and where interest in metascience inside the government is emerging alongside real disruption to the research enterprise. That combination is an argument for urgency: the window to shape how internal metascience capacity gets built may be shorter than anyone expected. A unit stood up quickly, without a protected budget or independent authority, narrowly focused on politically convenient questions, and with no plan for continuity — that’s a real risk. The design choices that prevent it aren’t complicated, but they have to happen early.
A metascience function that produces insights about peer review and grant mechanisms without building serious demand from program officers is the evidence community’s supply problem in a new form. A “Metascience Officer” role with no potential for career path or growth, no protected budget, no customer or audience, and competing responsibilities is the Evaluation Officer problem with a different name. Learning agenda questions about R&D mechanisms that nobody follows up on become checkboxes. Evidence that never reaches the room where program design decisions happen, regardless of its quality, has no impact.
Part of what makes institutional design so hard is that the distance between “we produced amazing insights” and “that knowledge changed anything” can be enormous. Experts at the Institutional Architecture Lab have a great framework here. They distinguish between institutions that produce knowledge (authoritative but loosely coupled to action), institutions that have knowledge formally embedded in decision processes (where findings must be engaged), and institutions where specific evidence thresholds trigger changes in practice. The Evidence Act was designed for the middle category and often ended up in the first.
Before we tell you where to go next, a note that applies to both communities: the questions metascience is asking aren’t exactly new inside agencies. Learning Agendas have been wrestling with peer review design, funding mechanisms, and portfolio effectiveness for years: imperfectly, under-resourced, but with real interest and curiosity. Arriving like you’re the first person to notice the building is on fire is a real pattern in the good governance world, and it’s one the evidence community sometimes got too good at before metascience got here. Ask what’s already been tried before you propose what’s next. It’s faster and it might save you from reinventing something that already didn’t work.
What to do instead: a checklist we wish we’d had
- Start with demand AND supply. Map the actual decisions agency leadership faces, like peer review redesigns, new funding mechanisms, portfolio rebalancing, and build the research agenda around those decisions instead of around what the metascience community finds most interesting. Before you build anything, build relationships with the people who will act on what you find. Understand what questions keep them up at night.
- Master the workflow problem. Know the decision calendar and what inputs people will actually read, in what format, and when. A finding that arrives after the window has closed doesn’t exist for practical purposes.
- Embed partnership in the working model. Co-design questions with program officers and make their success your success. Whether metascience becomes a resource people seek out or an office people avoid is something you can shape now.
- Take incentives seriously. Just because a metascience function exists doesn’t mean program officers will care, or that agency leaders will act on what it produces, or Congress will be curious. What are program officers actually rewarded for? What are agency leaders trying to protect? What would make peer reviewers engage differently with evidence about their own processes?
- Develop in-house capacity in addition to solid relationships with the outside. While it’s vital to find consistent and reliable communication paths between government and external research institutions, the government also needs some internal capacity to help be more responsive, flexible, and secure on time sensitive and issue sensitive questions.
- Design the talent model with purpose instead of happenstance. Is this a destination or a waystation? A fixed-term appointment that makes people more attractive when they leave, building an alumni network that carries the practice forward? Or a permanent career function that builds institutional memory? Both have a role: pure rotation and you lose institutional memory; pure permanence and you lose touch with the field.Think about where people come from, where they go, and what signal the function sends about whether this is meaningful work or a backwater.
- Build for durability. External accountability, cross-agency benchmarking, champions in OMB and Congress are what keeps a function alive across administrations. Build them early, when you have momentum and goodwill (by the way, though evidence work is still doing democracy good across government, the Evidence Team I led at OMB doesn’t exist anymore).
- Invest in relationships before you need them. One of the deepest structural failures in the evidence community was treating researcher-policymaker relationships as something that happened naturally, or that individual researchers could maintain on their own. Individual researchers can’t track decision-makers across election cycles, persist through staff turnover, or stay useful for years before they need anything back. And FAS research on local governments shows that policymakers often struggle to find the “front door” into research partnerships, even when they do want to build those relationships. The result is that academic engagement with policy tends to be episodic: it activates when someone needs something, fades when the grant or policy window ends, and depends entirely on who happens to know whom (there’s also interesting research by Max Crowley and colleagues that suggest all these ties are better built early in careers and levels of influence, on all sides). A well-designed metascience function has the ability to solve that “front door” problem – but should treat relationship-building as a core function, rather than assuming it will happen automatically, and invest in presence before anyone needs help.
The steps taken over the last several years to build federal evaluation capacity were good ones. The people who did that work were serious, and they built something real under difficult conditions. We hope this piece lands as what it’s meant to be: a love letter to that work, and a friendly peer review of the structural choices that will determine whether metascience does better
Successful Pooled Hiring Starts With Diving the Deep End
The Office of Personnel Management has been busily reversing course on federal workforce reductions with some splashy hiring announcements. In December, it launched Tech Force, a pooled recruitment effort targeting 1,000 early-career technologists to be placed across agencies for two-year stints. In March, it stood up across-government shared certificate for project managers. It launched an Early Career Talent Network spanning five job categories. Two weeks ago, it expanded Tech Force into cybersecurity. OPM Director Scott Kupor has been explicit about his ambition: this is a “model for more centralized, efficient hiring across government.”
I’ll bite: yes, there’s a lot of promise in that! The instinct behind all of these actions builds on years of initiatives meant to create efficiencies out of the hundreds of thousands of hires made federally each here. Pooled hiring, which should include one well-designed announcement, one shared assessment, and many agencies drawing from the same pool of qualified candidates, is exactly the kind of tool the federal government should be using. I saw this up close when I was at OMB and I fully drank this Kool-Aid. The logic is compelling: (typically) the federal government processes over 22 million applications and hires over 350,000 people into public service every year. No private employer operates anywhere near that scale, which I still believe can be an asset, and pooled hiring creates the entry point to get there.
But pooled hiring has a track record (going back several administrations), and it’s uneven. Most recently, the Biden administration championed it most ambitiously during the infrastructure surge, where OPM partnered with seven agencies and hired roughly 5,000 employees, doing things like USDA hiring 39 HR specialists off a single certificate (if this sounds underwhelming to you, trust me when I say it’s mindblowing to your average hiring manager; more explained shortly). But the same period produced plenty of pooled actions that generated duplicative work, agency foot-dragging, and candidates who aged off certificates before anyone made them an offer. FAS and others have been studying these challenges in the context of the permitting workforce surge, and the problems are structural, predictable, and repeating. Also? Solvable.
The concept has promise but implementation has kept breaking in the same places. This piece is about why and about how to get it right, now, while there’s political will and active momentum to use it.
The Design Error at the Center of Everything
First, a quick explainer on how this actually works — because “pooled hiring” gets used loosely and the mechanics matter. A pooled hiring action is a competitive job announcement run either by OPM centrally or by a lead agency on behalf of multiple agencies and intended to fill multiple open positions in multiple agencies. Instead of each agency posting its own announcement, recruiting its own applicants, and running its own assessment, one announcement goes out, one applicant pool forms, and one assessment process screens candidates into a shared certificate of eligibles (government-speak for a ranked list of candidates that agencies can choose from). Agencies that have signed on to participate can then make selections from that certificate without having to run their own action from scratch. OPM-run actions (like the current Tech Force or the project manager cert) work the same way, just with OPM as the lead rather than a single agency. Either way, the cert is the output: a ranked list of candidates who have been assessed as qualified, available to any participating agency to hire from without having to solicit new resumes, review their qualifications, administer assessments, or other tedious parts of the hiring process.
That’s the theory.
The shared certificate is where most implementations stop. Agencies get a screened list and then do their own thing — their own interviews, on their own timelines, with their own offer processes. Or maybe they don’t, even when they said they would! The coordination ends at the cert. Everything downstream remains fully siloed at each agency.
This is far from the ideal that most policymakers have in mind and what many private employers do. A genuine pooled hiring action pools the whole pipeline. Recruitment, assessment, interviewing, and offers — all coordinated, all running in parallel across participating agencies. That doesn’t work for every role, but in surge situations, or for roles where agencies make dozens of hires of the same roles every year, it’s great. Agencies don’t just agree to draw from the same pool. They show up on the same interviewing days. They make offers on the same compressed timeline. Candidates who applied once get considered by many agencies simultaneously with each running its own slow-motion version of the process.
Almost nothing the federal government currently calls “pooled hiring” actually does this. The new OPM actions are no exception. Tech Force is better marketed than previous efforts, and the private-sector partnerships are genuinely new. But the selection and offer stages remain siloed at each agency and I’ll be very curious if they make selections. That’s the design flaw everything else flows from.
What Breaks When You Don’t Fix the Design
When I was at OMB, we saw these failure modes up close, in what were probably deeply frustrating meetings with the valiant program team as we learned where the seams were. Some things we saw:
Pooled hiring worked when it was a clear administration priority and had OPM and OMB supplementation. Early indicators suggest that Tech Force has success because it’s clear that the administration, the OPM director, and OPM staff are both giving it attention and smoothing implementation behind the scenes. That’s good for proof of concept, but it doesn’t show the weaknesses that can emerge when administration accountability doesn’t hold agencies to delivery on innovation hiring methods.
Agencies didn’t trust screening they didn’t run. OPM’s own guidance requires agencies making selections from another agency’s certificate to verify that the original qualification and assessment criteria are appropriate for their position. That verification step becomes a second screening — which defeats the efficiency rationale entirely. Agencies that double and triple-screened candidates created more work than if each had run its own action from scratch. The fix isn’t better guidance, it’s building trust into the design upfront, by ensuring the people trusted with the most relevant subject-matter expertise help design the assessment in the first place.
Demand didn’t stay put. Agencies raised their hands, agencies or OPM ran a resource-intensive recruitment action, and then agencies were slow to hire — or circumstances changed before they did. The August 2024 OMB/OPM hiring memo specifically directed agencies to review available shared certificates before launching new hiring actions — a discipline that, if actually followed, would force better demand alignment upfront. It mostly didn’t happen and, absent the sort of prompting we talk about later, is hard to enforce. Partly this is a culture problem, but it’s also a structural one: agencies that don’t plan for talent surges find that new hiring needs don’t align with their existing workforce plans or their capacity to recruit, assess, and onboard. You can’t opt into a pooled action and then be surprised when the pool fills.
We struggled to tell the right people, and the system didn’t either. There’s a more fundamental problem sitting underneath the demand-alignment failure: hiring managers and HR specialists often don’t hear about pooled hiring announcements at all, and when they do, it’s generally not with enough lead time to actually prepare. Pooled actions get announced through OPM memos and Chief Human Capital Officers (CHCO) Council communications that circulate at the leadership level (and boy howdy did we circulate!), but that information doesn’t reliably travel to the hiring manager who is already three weeks into drafting a job announcement for the exact role sitting in a shared cert. And when it does arrive, it arrives as information: there’s no deadline attached, no checklist triggered, no reason to stop what they’re already doing. As it stands, among the 200K+ hiring managers, most made very few hires a year or in their overall career, so learning a process with barriers to entry was challenging.
Nothing interrupts the default action.The deeper problem is that nothing in the hiring workflow itself cues anyone to look. When a hiring manager initiates a new action in the hiring system, they’re not pushed or incentivized in any systematic way to check for an existing cert. When an HR specialist begins drafting a job announcement, no flag surfaces to say: a shared certificate for this position series already exists, do you want to use it? The system simply lets them proceed. This means that even when an agency or OPM has done the work of running a pooled action and producing a cert, agencies duplicate that effort anyway; less due to indifference, but because the path of least resistance is to do what they’ve always done, and nothing in the process interrupts that default.
The fix here is partly cultural but a lot technical. The Agency Talent Portal and USA Staffing need to surface available shared certificates at the moment a hiring manager or HR specialist initiates a new action for a covered position: as a required check embedded in the workflow itself. If you’re about to post a GS-12 data scientist announcement and there’s an active governmentwide cert for that exact series and grade, the system should tell you, right then, before you proceed. Opt-out, not opt-in. The current design assumes awareness that doesn’t exist and motivation that isn’t reliable.
Pooled actions were expensive for the “owner” and the experts: While cost-saving overall, running pooled actions could be resource and time consuming for the “owner,” and particularly the subject matter experts brought in for assessment, particularly when hires were not ultimately made.
The position description bottleneck. Pooled hiring inherits whatever good and bad planning exists in agencies’ position description (PD) libraries. Even for commonly-hired roles, position descriptions are not always readily accessible and, likewise, standard assessments often don’t exist at every grade level. But it’s a bigger challenge than that: the whole GS system presumes (competencies, job task analyses, and more) that every job is highly specialized, not generalizable for cross-agencies pools. FAS documented this directly: OPM and the Permitting Council collaborated to create a pooled, cross-government announcement for Environmental Protection Specialists — one job announcement producing a candidate list many agencies could use. But the assessment became a bottleneck because standard assessments didn’t exist for each grade level in the announcement, requiring significant additional development time. This isn’t an edge case, it’s a Tuesday. Breaking! OPM Director Kupor just announced a new AI tool to generate PDs! We’ll follow with interest.
Hiring managers couldn’t get access without a permission chain. For a new hiring innovation to be adopted, you’d think that all the barriers, incentives, and opt-in/out dynamics would be aligned. You’d be wrong. Pooled hiring at a “mother may I” architecture: system passwords and access, coordinators, gating processes, intermediaries between hiring managers and shared certificates. It’s a design flaw dressed up as compliance. The same 2024 memo had to explicitly direct agencies to update hiring manager permissions in the Agency Talent Portal. That it needed to be said tells you everything about how poorly the access question had been handled. As FAS and the Niskanen Center jointly documented in their analysis of the current OPM hiring memos, the toughest tasks are also the most crucial: changing the culture around hiring to empower managers, and actually letting line managers be managers.
Talent teams could be a good idea that keeps getting launched without the authority or resources to actually work. Every administration for the past decade has called for empowered agency talent teams — small, specialized units charged with driving hiring innovation, adopting new tools like SME-QA, and coordinating participation in pooled actions. M-24-16 explicitly called for agencies to create and sustain these teams, and the current OPM Merit Hiring Plan has stood one up at the central level as well. The concept has potential but execution has been consistently undercut by the same failure mode: no committed resources, no authority to intervene, no access, and no product mindset. In understaffed agency HR offices that were not empowered to “get to yes”, the function hasn’t meshed well, and moreover, it’s arrived in a system that already lacks strong strategic workforce planning, a key enabler of its potential success.
As FAS and the Niskanen Center documented agency talent teams, OPM communications and education support, and the necessary systems changes all require people, money, and IT investment that hasn’t materialized. Announcing a mandate is not the same as funding its execution.
But underfunding isn’t the only problem. Even well-resourced talent teams have struggled when they lacked the institutional standing to actually change agency behavior. The core failure mode is assuming that having good people in the building is enough — that talent solves problems on its own, without a clear theory of change about authority, access, and how decisions get made. An agency talent team that is advisory in nature, without a direct line to hiring managers and HR decision-makers, without leadership backing when they push back against entrenched process habits, and without metrics that create accountability for adoption, is not going to move the needle on pooled hiring participation. It’s going to produce reports and hold workshops and then watch agencies do what they were already going to do.
Veterans preference created confusion that nobody addressed proactively. Preference applies differently in delegated examining versus merit promotion contexts. When agencies share certificates across those lanes, legal ambiguity creates real hesitation. This is genuinely solvable — but only if OPM issues targeted guidance with each pooled action as a standard part of the launch package. Stepping back, it’s necessary to state that any type of absolute preference is going to make pooled hiring challenging. Clarifying guidance is a Band-Aid.
Small technical barriers compound the problem. One underreported friction point: shared certificate policies can constrain agencies from sharing certs across different geographic locations designated in the original announcement, or across different hire types — temporary versus permanent. An agency running a pooled action for DC-based positions can’t easily extend that cert to field office hires. A cert issued for permanent positions doesn’t smoothly cover term appointments. These are solvable technical problems that OPM and OMB could fix through policy revision but they require someone to actually map the barriers before designing the action.
And when agencies go it alone anyway, the burden multiplies for everyone. This is the part that gets lost in discussions that treat siloed hiring as merely inefficient rather than actively harmful. When agencies that are already understaffed — particularly permitting and HR teams — don’t leverage opportunities to work together, bottlenecks compound. Pooled hiring isn’t just a convenience for well-resourced agencies. For teams that are already stretched, it’s the difference between a manageable workload and an impossible one.
Agency HR leads without the skills or network to work across agencies. Like so much else, pooled hiring depends on relationships. OPM and agencies have not carefully selected the HR managers who not only understand the potential policy barriers to working across agencies but the collaboration skills and networks to solve problems quickly.
The Assessment Question: Use the Right Tool Not the Easy One
If you’ve read this far, you’ve probably heard of things like SME-QA, the greatest acronym in the hiring world. Let’s talk assessments.
The default federal hiring assessment — the self-assessment questionnaire — is effectively worthless for identifying technical talent. As Jennifer Pahlka has put it, the system has been built so that the most important knowledge is how the hiring process works instead of the knowledge needed to do the job. A nationally recognized programmer once applied to the Department of Defense and was initially rejected because their resume described real expertise in language that didn’t match OPM’s classification keywords. Meanwhile, someone who understood the system could mark themselves “expert” across every self-assessment category with no verification at all.
The Subject Matter Expert Qualification Assessment, or SME-QA, was one of the skills based hiring toolkits developed to fix this: real experts screen for real skills, with HR ensuring merit principles hold. SMEs independently review every resume. Candidates who clear the initial bar then go through further steps like structured interviews, coding exercises, or written assessments — administered by other practitioners in the field, not generalist HR staff. For technical roles going into a pooled action — data scientists, cybersecurity professionals, engineers — SME-QA paired with a shared certificate is close to the ideal design. Build the assessment once with governmentwide SME input, share the cert, and every agency draws from a pool that was actually screened by people who know the field.
But any skills based hire practice has a scaling problem that’s been documented since the first USDS pilots. The work is resource intensive for federal agencies not used to dedicating so much SME time to a hiring process. As Niskanen’s recent analysis of the Chance to Compete Act makes clear, new written assessments developed by industrial-organizational psychologists are extremely resource-intensive to produce — likely prohibitively expensive at the scale needed to cover broad swaths of the federal workforce. But there are roles and moments where such dedicated investment makes sense.
The design principle that should govern this: pooled hiring should be an opportunity to concentrate assessment burden at the enterprise level, not multiply it at the agency level. Build the assessment once, or maximize use of SME-QA time, governmentwide, for roles where it genuinely matters. Actually use them consistently rather than rebuilding from scratch at each agency. And as Niskanen argues, transform OPM’s role from compliance monitor to assessment engine: a marketplace of vetted, shared tools agencies can pull from rather than commission independently.
There’s a trust dividend here too. Agencies that contribute subject-matter experts to the assessment design have far more reason to trust the resulting certificate. Skin in the game at the assessment stage translates directly to confidence at the hiring stage.
A Note On Listening
Many successful pooled actions worked because OMB and OPM (or other senior White House offices) gave attention, capacity, authority and accountability to the process, bolstering agencies who were being asked to execute hiring with unusual flexibility and competence.
Overall, however, when agencies told OPM and OMB that pooled hiring was hard for them to execute alone, the response from the center was too often some version of: the guidance is out there, the instructions are online, that’s how the process works. Agencies described a cascade of rigidities that made implementation genuinely difficult, and we weren’t always responsive. We treated compliance problems as communication problems. If agencies weren’t doing it right, they must not have understood it correctly, so the answer was more guidance, clearer FAQs, better webinars.
That’s the wrong diagnosis. What they were telling us was that the process didn’t fit their reality and that the gap between what the policy assumed and what their operations actually looked like was wide enough that no amount of additional instruction was going to close it. When the people responsible for carrying out a policy are consistently telling you it’s hard in specific, consistent ways, the right response is to ask what’s broken in the desig.. The people designing these systems need to hear that feedback as signal instead of as resistance to be overcome.
This is the reason why the recommendations in this piece are about structural changes to how pooled hiring is designed, not about better outreach or clearer communications. Agencies don’t need another memo explaining how shared certificates work. They need a system that works in the conditions they’re actually operating in.
How to Actually Do This Right
The current OPM actions are a real opportunity. Here’s what would make them work, stated as plainly as possible.
Lock in real demand before you launch. Not expressions of interest: actual hiring commitments with funded billets and named positions. The failure mode is OPM building a pool that agencies shop from slowly or not at all. Require agencies to submit hiring forecasts before they’re included in a pooled action, and hold them to those forecasts with visible accountability.
Build assessment infrastructure before the announcement goes up. Standardized PDs, validated assessments, and clear SME selection criteria that agencies trust need to exist before the action launches. Thecentralized position description library called for in M-24-16 is the right vehicle. Critically, assessments need to exist at every grade level included in the announcement.
Build the awareness and the system prompt together. Upgrade communication on pooled hiring announcements directly to hiring managers and HR specialists. But communication alone won’t fix this. The Agency Talent Portal and USA Staffing need to surface available shared certificates at the moment a hiring manager or HR specialist initiates a new action for a covered position series and grade. This should be a required check embedded in the workflow itself — before they proceed with drafting a new announcement. If you’re about to post a GS-12 data scientist announcement and an active government-wide cert exists for that series and grade, the system should tell you right then. The current design assumes awareness that doesn’t exist and motivation that isn’t reliable.
Pool the interviewing, not just the screening. Coordinated interviewing days. Same-day or 48-hour offer authority for hiring managers. Agencies competing for the same candidates simultaneously, not sequentially. Cross-agency onboarding cohorts that start together and build peer networks from day one. This is what actually compresses time-to-hire.
Fund and empower talent teams as implementation infrastructure. Every idea in this piece requires someone inside each major agency whose job it is to make that happen. That’s what a talent team is for. But talent teams need three things that they rarely get: a dedicated budget line, direct access to the hiring managers and HR leadership they’re supposed to influence, and metrics that hold them accountable for adoption rates and actual hiring outcomes rather than process activity. A talent team of one person with a shared budget and no senior sponsor is not an implementation strategy.
Give hiring managers direct access. Update the Agency Talent Portal permissions. Eliminate the intermediary layers between a hiring manager and a cert they’re authorized to use. Hold managers accountable for whether they hire. Culture change here is real but it follows structural change: when managers have direct access and clear authority, behavior shifts.
Make follow-through a metric with teeth. Agencies that opt in and don’t hire should have to explain why, publicly, to the President’s Management Council.The voluntary participation problem doesn’t get solved with please-and-thank-you memos.
Run continuous pooled actions for common roles. HR specialists, contracting officers, environmental specialists, IT managers — these aren’t surge needs, they’re permanent ones. A cert that’s always open, with agencies drawing from it as needs emerge, is far more useful than a prestige program that runs once a year and then goes quiet.
The Bigger Lens
(with thanks to Gabe Menchaca and Peter Bonner for making the stronger argument)
Pooled hiring is a microcosm of a question the federal government seesaws on constantly: what does it mean to govern as an enterprise rather than as several hundred agencies that happen to share a payroll source?
This requires admitting something those of us who have worked in the center don’t always say plainly: agencies and their leaders are protecting their turf for understandable reasons. They are accountable for their missions, their budgets, and their outcomes. When a pooled hiring action asks them to trust a cert they didn’t design, coordinate interviews around a shared calendar, and accept that they won’t get every single thing they want, and that’s a big ask! The trade may be worth making, but it doesn’t happen automatically, and the center has not historically done a good job making the case for why, or building the conditions under which agencies can actually say yes.
That’s a collective action problem, and it’s harder than it looks. It requires genuine leadership alignment across all the agencies involved, and a center that has made the benefit of cooperation concrete and visible rather than just asserting it in guidance. Too often the response to non-participation has been more documentation rather than an honest look at what the actual barrier was. That’s compounded by a structural problem worth naming: agencies are accountable for their HR outcomes but OPM holds much of the compliance authority over how hiring gets done. Accountability without authority produces exactly the behavior you’d expect.
The federal government has demonstrated it can operate differently. The BIL surge, the data scientist certs, USDA’s HR specialists (and maybe Tech Force) worked because the conditions were right: shared design, locked-in demand, leadership alignment, enough urgency to overcome the default toward agency autonomy. The question is whether we can build those conditions deliberately rather than stumbling into them during a crisis. That requires a solid theory of change about how cross-agency infrastructure actually gets adopted: one that takes agency self-interest seriously as a design constraint rather than an obstacle to be overcome by memo. Get that right, and pooled hiring becomes a model for how the federal government decides what to do together and what to do apart. That’s a bigger prize than faster hiring. It’s a more functional government.
Strengthening the Federal Cycle of Learning and Adaptation by Closing the Loops
The federal government has a feedback-loop problem.
Regularly generated information, including evidence, performance information, and qualitative insights from implementation, too often fails to shape decisions. Evidence may be reviewed without changing priorities; performance data may be tracked without clarifying what it informs, and implementation feedback may reach leadership without surfacing what works for whom and why, or suggesting next steps. The components of a cyclical learning system linking priorities, questions, evidence, decisions, and implementation information exist in theory and on paper, but the connective tissue that turns all of these components into a functioning cycle of learning and adjustment is lacking. Information and artifacts alone don’t necessarily facilitate learning and adaptation; strengthening federal feedback loops requires embedding translation and use into decision-making from the start.
This memo is not a case for new infrastructure. The Evidence Act, learning agendas, evaluation plans, performance frameworks, and customer experience authorities already exist; what they do not yet add up to is a learning system. The translation this memo proposes is turning the infrastructure we have into the learning system we need, and it’s addressed to federal program leaders, policy officials, evaluation and evidence staff, performance officers, and strategic planning teams who already sit inside it and are best positioned to make it function as intended.
Challenge and Opportunity
The federal government already operates within a broad cycle of goal-setting, evidence generation, performance review, implementation, and reporting. On paper and in principle, this cycle should allow for learning, adjustment, and improvement to federal programs over time. In practice, however, agencies vary in how consistently they translate such information into planning, decision-making, or course-correction. Federal agencies have made progress in building and using evidence, but translating that information into timely operational or policy revisions remains uneven.
The core problem isn’t production; it’s translation, and the translation failure shows up as “so what” gaps on both sides of the information pipeline. On the input side, receivers of information are often left asking what they’re supposed to do, and on the output side, a second question appears – “is it my job to act on this, and if so, how?”. Research findings are often too slow, too caveated, or too disconnected from immediate policy and management questions. Performance data may show quantitative changes in outputs, costs, or enrollment without revealing the mechanisms behind them or the practical implications for implementation, or cueing the design apparatus that could apply these insights. Feedback from frontline service providers and affected users might reach leadership mainly through quantitative indicators, dashboards, or status updates, which don’t always capture lived experience, causal explanation, or informed suggestions for course correction. Without named owners and defined next steps, even the most actionable information tends to circulate rather than convert.
Three gaps sit behind this pattern. First; a context gap – decision-makers often lack the full picture, because qualitative indicators and customer experience research arrive separately, or later than quantitative evidence, leaving them with only a partial view of what’s working well or driving implementation problems. Second, an action gap; even with a complete view of the picture, it’s not always obvious which lever applies, on what timeline, or with what tradeoff. Third, an ownership gap; it’s often unclear who is responsible for translating any given signal into a decision, and this ambiguity means that insights can be observed without being acted on. Together, these three gaps leave evidence and feedback insufficiently integrated into decision-making routines.
The problem is also structural; decision-makers face turnover, competing priorities, time limits, and management pressures, and thus, evidence needs a more robust pathway. Devoid of clear translation, trusted messengers, and defined or mandated use points, even the most relevant information can be too late, too ill-timed, or too jargon-heavy to influence decisions, resulting in missed adaptation opportunities.
The federal government doesn’t need an entirely new learning architecture. It needs to make the one it already has more usable. Agencies can do this in a few ways. First, by building stronger translation functions by creating space for “knowledge brokers” (people or teams whose core function is to translate evidence into decision-relevant language and maintain the required relationships that make the translation trusted). Second, by incorporating the use of evidence, performance, and implementation feedback into policy and program work from the start. Third, by creating better pathways for implementation and lived-experience feedback to reach leadership in ways that resonate with them and support action.
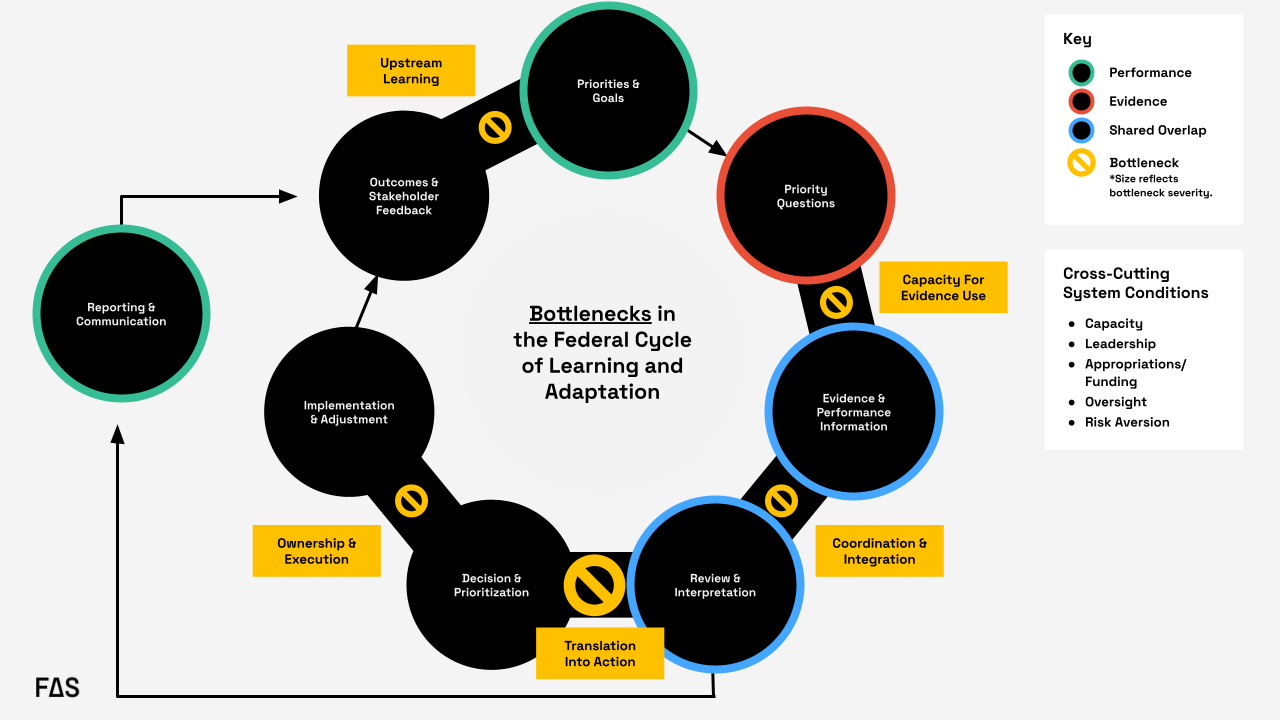
Formal federal guidance envisions a closed “loop” linking goals, priority questions, evidence, and performance information, along with review, decision-making, implementation, reporting, and feedback. In practice, the loop often degrades at key handoffs: evidence-use capacity, coordination and integration, translation into action, ownership and execution, and upstream learning from outcomes. The most significant recurring bottleneck occurs during the transition from review and interpretation to decision and prioritization, where information is generated and reviewed but does not reliably translate into action.
Plan of Action
We need to shift from a system that collects information to a system that uses it.
Agencies should create or strengthen embedded translation functions that connect evidence, performance information, implementation experience, and policy levers at the moment decisions are being made. The key is to move from a dissemination model to a utilization model. Instead of “produce, disseminate, and hope for uptake”, agencies should do the following:
Recommendation 1. Designate a knowledge broker to facilitate regular decision briefs…
or routines that create structured opportunities to clarify what’s known, what’s uncertain, and what actions are available – beginning with a defined set of high priority issues rather than every single decision the agency needs to make.
This recommendation targets the translation into action bottleneck in Figure 1; the handoff from review and interpretation to decision and prioritization, which can be considered the most significant recurring point of failure in the federal cycle of learning and adaptation. In practice, this means assigning this function to a role or small team housed in an existing performance, evaluation, strategy, or program office and requiring that group to support recurring decision points with short decision briefs. Those briefs should identify the decision, synthesize relevant evidence, performance trends, and implementation feedback, and specify available actions, tradeoffs, and owners.
For example, in the rollout of the FAFSA Simplification Act, a knowledge broker tied specifically to this initiative could have translated readiness indicators, beneficiary feedback, and information from financial aid administrators into decision-ready synthesis for the officials with decision authority who were attempting to course correct in real time. Instead, significant delays turned the rollout into a high-profile implementation issue.
Crucially, this function should start narrow. Rather than positioning a knowledge broker as an all-purpose translator for an agency’s full decision load, the initial portfolio could be scoped to a small set of priority issues. Starting narrow lets the broker establish credibility and relationships that make translation trusted and refine what the routine and explicit outputs are before it scales – the portfolio can scale later. This gives agencies a defined mechanism for turning reviewed information into decisions rather than leaving that handoff informal. Within the federal government, the Office of Evaluation Sciences has modeled how an embedded team of evidence translators can work alongside program offices rather than from a silo.
Recommendation 2. Start policy initiatives and evaluation planning with a real question…
or decision, identify the user, specify the lever, and clarify – in advance – what different findings would imply. Incorporating this thinking upstream changes the role of evidence from a retrospective input to an operational tool.
This recommendation mainly addresses the translation into action bottleneck, and secondarily, the evidence-use capacity bottleneck. Agencies can operationalize this by building decision framing into existing learning agenda and evaluation planning processes, both of which are already required under the Evidence Act. Before an evidence product is commissioned or a performance indicator is selected, program offices can be required to answer four questions on the record: What decision is this for? Who will use it? What lever would change as a result? What finding would lead to what action?
In a hypothetical example, say that USDA’s Food and Nutrition Service (FNS) wants to commission a new evaluation or analysis regarding SNAP redetermination churn (the pattern of households losing SNAP benefits at recertification and then re-enrolling, often for procedural reasons rather than eligibility). The four questions noted above can be answered on the record before the work begins. The decision is whether to issue new guidance to state agencies on recertification practices and what that guidance should encourage. The user is the FNS administrator and the relevant policy office, with state level SNAP directors as the implementing audience. The lever is subregulatory guidance. The early thinking regarding mapping findings to actions would specify, in advance, which patterns or insights would trigger which associated response. This way, when the findings arrive, USDA wouldn’t be starting from scratch with the “what do we do with this” question; the decision architecture would already be in place.
Pre-specifying these conditions in a short decision-framing memo that travels with the work turns evidence from a retrospective deliverable into a tool scoped to a specific decision or policy window. The same logic extends to decision memo templates themselves, which can include standing prompts such as “what evidence informed this decision?” and “how will we learn about this in real time?”, so that utilization is built in.
Recommendation 3. Create pathways for easier access to mixed methods evidence and insights from lived experience.
Recommendation 3 targets the coordination and integration, and upstream learning bottlenecks; the gap where evaluation, performance, administrative, qualitative, and customer experience data move at different speeds, live in different places, and reach decision-makers as parallel streams. Insights from lived experience – what programs actually look and feel like to the people using them – are particularly likely to be separated from information that reaches leadership, arriving as anecdotes, if they arrive at all. Because these problems are distinct; the recommendations can be broken down and addressed at the agency level.
Recommendation 4. Standardize decision-ready formats that consolidate quantitative and qualitative evidence.
Agencies should build standardized decision templates and briefs that present quantitative indicator-level data alongside narrative summaries of lived experience and implementation conditions, so decision-makers aren’t expected to synthesize across disparate sources on their own timelines. The resulting artifacts should be tied to recurring decision moments (budgeting, guidance revisions, program reauthorization) so that they can be used in real time.
In the FAFSA Simplification Act rollout, the Department of Education leadership faced this problem: application data, technical readiness indicators, information from financial aid administrators, and user feedback existed separately, and moved at different speeds. A standardized decision-ready format could have pulled those streams together; pairing completion trend data with brief narratives or exemplary quotes regarding what applicants and financial aid offices were actually encountering, rather than leaving leaders alone to assemble the picture in real time
Recommendation 5. Actively use existing general clearance mechanisms for rapid qualitative and user experience research.
Agencies should make use of standing generic clearance mechanisms that allow them to fast-track small qualitative and user experience studies (for example, up to 100 respondents, completed within a fixed time window) when unexpected findings need rapid explanation. This would allow for the ability to run a tightly scoped evaluation in weeks rather than months, which is the operational timescale at which decisions frequently move. Without it, the qualitative evidence needed to explain any type of performance anomaly often arrives after the decision or policy window has closed.
For SNAP redetermination churn, this would let FNS turn around a short, scoped evaluation of why participants are dropping off at a specific step in the recertification cycle in weeks rather than months. The insights could then inform the next round of guidance rather than coming in after the fact.
Recommendation 6. Build customer-first indicators built into existing federal reporting requirements.
Beneficiary and frontline experience should become part of the evidence base by default rather than by exception. Most federal programs already have reporting infrastructure, and layering in a modest set of customer-first indicators that use the existing infrastructure rather than building new information collection requirements ensures that user perspectives are consistently available as routine inputs.
Within the federal government, the customer experience and life experience work coordinated through OMB and performance.gov has demonstrated that lived experience can be collected and used at scale within existing authorities, which can be considered a foundation to build from rather than reinvent. At the state level,Minnesota’s Story Collective, housed within Minnesota Management and Budget (MN MMB), pairs administrative and performance data with qualitative, lived-experience narratives to give decision-makers a richer view of what their programs are actually producing.
These recommendations also address a common weakness in the federal system: evidence and performance information sit within the same broad ecosystem but move at different speeds, use different tools, and often reach different audiences. This is all the more reason to create a translation layer that can synthesize across them. Agencies need staff and routines that can connect evaluation, administrative data, performance indicators, qualitative input, and implementation realities into decision-relevant guidance. Without that connective tissue, agencies are left with parallel streams of information that don’t consistently converge at the point where action occurs.
Conclusion
The federal government already generates a great deal of information about what it’s doing and how it’s performing, but information isn’t the same as learning, and learning isn’t the same as adaptation. The gap between them is where the “so what” goes unanswered, and where the federal feedback loop breaks down.
Closing these loops doesn’t require new infrastructure or authority. It requires three shifts in how the existing system is used: designating knowledge brokers to carry translation across the handoff from review to decision-making, building decision framing into policy and evaluation work from the start so that evidence is scoped to the decisions it’s meant to inform, and creating pathways that move mixed-methods and lived experience into decision-makers’ hands in formats and timeframes that match how decisions actually happen in the federal environment. Whether the question is about USDA responding to SNAP redetermination churn or the Department of Education learning from an application rollout in real time, the underlying pattern is the same: the signals exist, but the translation that turns signals into actionable insights doesn’t reliably happen.
If the government wants a system of learning and adaptation that improves results in real time, it has to treat translation, utilization, and adaptation as core functions of governance rather than as afterthoughts.
Outcome-Based Contracting Reorients Government IT Acquisition Around Public Value and Mission Results
The effectiveness of federal programs is increasingly determined by the technology that powers them. Yet decades of oversight and research have documented persistent challenges in large-scale IT modernization. The Government Accountability Office has repeatedly designated federal IT management as high risk, citing cost overruns, schedule delays, weak requirements management, and inadequate oversight. Bent Flyvbjerg’s research shows that large public-sector technology and infrastructure programs are especially prone to failure due to scope creep and cumulative risk. The Defense Innovation Board similarly concluded in Software Is Never Done that long development cycles and early requirement lock-in expose missions to unacceptable risk.
Across these analyses, the pattern is consistent: requirements are defined too early and too rigidly; performance is measured too late; incentives reward milestone completion rather than operational outcomes; and risk accumulates until deployment. These failures reflect several structural challenges—fragmented funding, leadership turnover, legacy system complexity, and acquisition models that delay validation and limit adaptation.
Traditional acquisition approaches assume stable requirements and predictable environments. Software-intensive systems do not behave this way. Requirements evolve, dependencies emerge during implementation, and technology ecosystems shift over the life of the contract. In this context, specification-driven models can increase risk by delaying feedback and limiting course correction.
This paper examines Outcome-Based Contracting (OBC) as a model for aligning acquisition with the realities of modern IT delivery. OBC reframes procurement around the staged achievement of measurable mission outcomes rather than the delivery of predefined technical artifacts. OBC ties funding, evaluation, and continuation decisions to mission outcomes and pairs naturally with iterative delivery practices that surface and reduce risk early.
Outcome-Based Contracting
Federal acquisition models have evolved over time in response to changing technologies and risks. Early approaches emphasized detailed specification and cost control, with contracts structured around defined requirements and reimbursement of inputs (e.g., cost-plus and fixed-price models). As systems grew more complex, performance-based contracting emerged to shift focus from activities to measurable outputs and service levels. However, in complex and dynamic environments, even performance-based models often remain tied to predefined deliverables and intermediate metrics, limiting their ability to adapt as conditions, requirements, and understanding evolve over time.
Outcome-based contracting (OBC) represents a further evolution. It structures the government–contractor relationship around shared accountability for mission results rather than delivery of predefined outputs. Its defining feature is not a pricing model, but the alignment of incentives, governance, and performance measurement around measurable mission outcomes.
As Allan Burman notes, building on performance-based contracting, OBC shifts accountability from activities and milestones to mission outcomes. In practice, it establishes a structured process in which government and contractor jointly deliver measurable results, with contracts defining decision rights, evaluation mechanisms, and adaptive processes.
Key features include:
- Shared accountability: success is defined in operational terms, not artifact delivery
- Collaborative outcome definition: the government defines the problem to be solved, contractors propose and refine approaches as evidence emerges
- Adaptive performance management: metrics guide decisions, not just compliance
- Joint problem solving: governance supports rapid adjustment when performance diverges
A useful way to understand outcome-based contracting is as a managed performance relationship rather than a one-time procurement transaction. As research from the IBM Center for The Business of Government emphasizes, effective outcome-based models require clearly defined desired results, measurable indicators of success, and ongoing performance management processes that allow both parties to assess progress and adjust course. This includes establishing baseline performance, continuously monitoring results, and linking financial incentives, contract options, and governance decisions to demonstrated improvement. Critically, these models depend on sustained collaboration and transparency: agencies must be able to interpret performance data and engage in joint problem-solving with vendors, rather than relying solely on compliance reviews. In this sense, OBC is not simply a different way to write requirements—it is a different way to manage delivery, in which measurement, incentives, and decision-making are continuously aligned to achieving mission outcomes.
Applying Outcome-Based Contracting to IT Modernization
Applying OBC to IT modernization requires three shifts: defining measurable outcomes, structuring decision rights, and organizing contracts around incremental delivery.
Defining outcomes
Mission objectives must be translated into measurable operational indicators—such as transaction completion rates, time to resolution, system availability, or error reduction. These indicators must be precise enough for evaluation while reflecting real-world service performance.
Effective models distinguish between:
- Mission-level outcomes (stable): e.g., reducing time to receive benefits
- Implementation metrics (adaptive): e.g., response times or interim system thresholds
For example, a call center contract might set a mission outcome of reducing resolution time by 30 percent, supported by metrics such as speed of answer, first-contact resolution, and callback completion time.
A central design question is how outcomes are embedded in the contract. Outcomes can function as binding accountability anchors, linked to evaluation, incentives, and option decisions, but not as rigid end-states. This approach is only effective when supported by governance structures that allow agencies to interpret performance and adjust delivery.
Critically, outcomes and the underlying problem definition must be treated as testable and subject to refinement. Initial problem framing is often incomplete in complex systems. Contracts and governance models should therefore include regular check-ins, using data, user research, and operational feedback to assess whether the problem is being solved as intended. Where necessary, agencies and vendors must be jointly empowered to restate or refine the problem to ensure continued alignment with mission needs.
Structuring decision rights
OBC requires clear decision making authority over priorities and tradeoffs. In software delivery, this centers on a strong government Product Owner (PO) role. The PO is responsible for backlog prioritization, acceptance criteria, and aligning delivery with mission outcomes. The PO must be empowered to continuously adjust priorities based on user needs and performance data without requiring contract modifications. Contractors are accountable for delivering measurable progress, but do not control mission priorities.
Governance must reflect agency maturity, and also the nature of the initiative. More mature organizations can rely on PO-driven execution and adaptive metrics, using contract outcomes as high-level anchors. Even in less mature agencies, OBC principles can be applied in targeted ways—particularly in user-facing systems or components where outcomes can be clearly measured. In some cases, especially large enterprise system implementations, hybrid approaches may be required. These may combine clearly defined objectives and outcome metrics with more structured implementation phases for core platform rollout. The key is not strict adherence to a single methodology, but aligning decision rights, outcomes, and delivery approach to the realities of the system being implemented.
Structuring incremental delivery
Contracts must support incremental, evidence-based delivery. Large, multi-year programs defer risk discovery until late in the lifecycle. Iterative delivery reduces this risk by shortening feedback loops: capabilities are deployed incrementally, evaluated under real conditions, and adjusted early. Incremental delivery provides disciplined mechanisms for iteratively paying down risk.
OBC complements this model by tying funding and continuation decisions to demonstrated performance. Agile practices surface risk; OBC aligns accountability and resources to its mitigation.
This has direct implications for funding models. Effective OBC implementations require upfront decisions about how much funding is allocated to a product or service, with mechanisms to adjust that funding over time based on performance. Budgeting should support iterative scaling—expanding or contracting investment based on whether outcomes are being achieved. This, in turn, requires financial flexibility, such as capability-based budgeting, and the ability to reallocate funds or leverage working capital-like mechanisms.
In practice, appropriations constraints can limit this flexibility. For example, agencies operating under single-year appropriations may struggle to dynamically adjust funding in response to performance signals. Addressing this requires coordination between acquisition, product, and financial management functions to ensure that funding structures align with the adaptive nature of outcome-based delivery.
Outcome-Based Contracting In Practice
Outcomes-oriented approaches are not new but remain underutilized in IT acquisition. Existing models demonstrate the value of aligning funding to measurable performance.
Within government, the Department of the Navy’s World Class Alignment Metrics (WAM) evaluates IT investments based on outcomes such as resilience, customer satisfaction, and cost per user. Similarly, Department of Defense Performance-Based Logistics ties compensation to readiness outcomes, and NASA’s Commercial Crew program links payments to demonstrated capability.
These examples share a core principle: funding follows validated performance rather than predefined inputs. Applied to IT modernization, this requires pairing mission outcomes with iterative delivery, clear decision rights, and sustained technical engagement. Without these elements, outcomes risk becoming abstract goals rather than operational tools.
Despite its advantages, outcome-based contracting is not the default in federal IT acquisition. In practice, existing incentives continue to favor specification-driven models: funding structures are rigid, oversight emphasizes compliance with predefined requirements, and procurement processes reward detailed up-front definition over adaptive execution. The following case illustrates how these dynamics shape real-world outcomes—and how leadership, governance, and delivery choices ultimately determine whether programs succeed or fail.
Case Study: SSA Call Center Modernization
The Social Security Administration (SSA) operates one of the largest public-facing service platforms in the federal government, serving approximately 70 million Americans through its national 800-number network and field offices, processing high volumes of calls. In 2017, the SSA faced growing problems with its aging, complex telephone infrastructure and rising wait times for the tens of millions of Americans who rely on the agency’s national 800-number for assistance with benefits, Social Security numbers, and other services. To address these issues, SSA launched the Next Generation Telephony Project (NGTP), a large IT modernization effort intended to replace legacy telephone systems and unify call handling across the agency.
NGTP emerged from a traditional acquisition model: a detailed, waterfall-style specification, a large systems-integrator contract, and milestone-based progress tied to predefined technical requirements. In February 2020 SSA awarded an IDIQ contract to Verizon to design, implement, test, transition, operate, and maintain the new telephony platform, including procurement of hardware, software, and services. Implementation faced challenges from the beginning: Verizon’s win was contested, delaying the start of work. SSA’s team didn’t realize the solution Verizon proposed, reinforced by SSA’s own contract requirements, was based on architectural components that were a generation behind leading contact center systems. NGTP’s 10-year planning horizon meant any solution would likely be obsolete before full deployment.
By 2020, with the project still in early development, the COVID-19 pandemic forced SSA call center agents to work remotely — a capability the existing legacy system lacked. Verizon scrambled to assemble a custom stopgap solution, but this was plagued with issues. From May 2021 to December 2022, over 40 service disruptions caused dropped calls, long wait times, and outages. At times, more than half of calls went unanswered as the team capped incoming calls to maintain system stability.
Meanwhile, NGTP suffered further delays and technical hurdles. SSA executives were frustrated but assumed they were contractually stuck. The system finally launched in December 2023 for the 800-number only, delivering just part of the promised functionality. But the system experienced ongoing performance issues, including increased wait times and disconnected or unanswered calls that hindered the agency’s ability to serve the public. On August 22, 2024, after only about 10 months of operation, SSA transitioned the 800-Number Network off the NGTP platform and moved to a different telephony solution. The NGTP project cost SSA over $160 million and was abandoned within a year of deployment, with the agency reverting to an alternative telephony platform.
The failure was not attributable to a single cause. Interviews and oversight findings point instead to a combination of over-specification, missing mission outcomes, weak accountability mechanisms, long planning horizons, and an acquisition structure that made adaptation difficult.
It is also important to recognize the scale and complexity of SSA’s operating environment. The agency’s service delivery depends on hundreds of interdependent systems, many of which encode decades of policy and operational logic. Modernization efforts must contend not only with outdated technology, but with deeply embedded business rules and integration dependencies that are not always fully visible at the outset. These conditions increase the difficulty of both specification and implementation, regardless of acquisition approach.
Specificity Did Not Produce Control
A central lesson of NGTP is that specificity in requirements does not necessarily translate into control over outcomes. The solicitation and technical requirements were extensive and highly prescriptive. They incorporated staff input but lacked sustained user-centered validation and focused heavily on defining technical components rather than the operational outcomes the system was intended to achieve. In several cases, the contract mandated architectural approaches that constrained flexibility and effectively locked the program into solutions already lagging prevailing commercial practice.
The NGTP contract required the development of significant custom telephony capabilities in a market where mature commercial Contact-Center-as-a-Service (CCaaS) platforms already existed. Custom software and hardware development inherently carries greater risk than configuring established commercial platforms: the first buyer bears the cost of defects, scaling problems, and design errors that mature products have already identified and resolved. As a result, the program assumed substantial technical risk without clear evidence that SSA’s mission required a bespoke system.
The decision to pursue a custom telephony architecture also introduced structural technical risks. The system was intended to function as a “single enterprise contact center” capable of routing calls across SSA’s national network. In practice, however, the implemented solution consisted of six separate contact centers operating as independent queues rather than a unified system. According to the SSA Office of Inspector General, this configuration prevented calls from being dynamically rerouted between queues, limited agents to answering calls from a single queue, and could disconnect calls when agents logged out of one queue even if capacity existed elsewhere in the system. These limitations increased wait times and created operational inefficiencies. Efforts to resolve the architectural mismatch led to the development of a custom routing “brain” intended to connect the six queues—effectively reinventing load-balancing technologies that have been widely used and commercially mature for decades. The need to retrofit this architecture required multiple contract modifications and created ongoing operational challenges. As one SSA leader later observed, “Some people on the project might have known that load balancers had been mature for 30 years, but managers weren’t listening to them.”
The contract’s prescriptive structure also undermined the flexibility typically associated with its contract vehicle. Although NGTP was structured as an IDIQ, the narrowly defined solution space meant that many necessary adjustments required formal work orders or contract modifications. In practice, the program combined the administrative rigidity of traditional contracting with the technical risk of custom system development.
The detailed specifications locked the implementation into many types of outdated architectural assumptions. For example, certain components were required to be compatible with an old, yet unspecified, version of Internet Explorer, a browser Microsoft formally retired in 2022 in favor of Microsoft Edge. Rapidly evolving technology environments can render highly specific requirements obsolete before systems are delivered. At the same time, the extensive technical detail did not fully address practical operational considerations, such as ensuring that existing SSA call center staff could easily access and use the system in their day-to-day workflows.
Missing Mission Outcomes
The NGTP case also illustrates the limits of operator-focused metrics. SSA understandably focused on call volume and the ability of the system to handle surges in demand. Previous infrastructure could “top out” during predictable spikes, such as cost-of-living adjustment periods. Capacity therefore became a central concern.
But throughput alone is not the same as service performance. For beneficiaries, the meaningful outcomes include how long it takes to reach a representative, whether the issue is resolved on the first contact, how many interactions are required, and how long it takes to complete a request. Those mission outcomes were not adequately embedded in the contract’s performance framework.
Metrics such as average speed of answer did not fully capture the user experience, particularly when calls were dropped, or handled initially by automated systems, or callbacks were counted in ways that reduced reported wait times without necessarily reducing the time required for beneficiaries to obtain help.
The deeper problem was architectural as well as contractual. SSA’s call center is best understood as a front-end interface to a much larger, deeply complex service delivery system involving eligibility determination, identity verification, claims processing, and payments. Yet the contract largely treated telephony modernization as a standalone technical problem rather than as part of an integrated operating model. This narrow framing also limited foresight into how the capability could evolve over time, adopting future emerging technologies or adding integrations with other agency systems to support an omnichannel service model. Defined primarily within a technical infrastructure context, the effort optimized for telephony components rather than positioning customer service as a strategic, cross-agency capability.
Accountability Was Weak Where It Mattered Most
Federal acquisition frameworks already provide multiple mechanisms for vendor accountability, including service level agreements (SLAs), financial incentives and penalties, option periods tied to demonstrated progress, and formal performance reviews. In the private sector, large IT and service contracts routinely embed such operational standards like uptime guarantees, response-time thresholds, incident-resolution timelines, and financial penalties for failure to meet them to ensure that vendors remain accountable for system performance under real operating conditions. In the NGTP case, however, these mechanisms were not sufficiently embedded in the contract structure or tied to mission outcomes and enforceable operational standards.
The SSA Office of Inspector General found that the NGTP contract lacked sufficient performance-based quality standards and incentives to ensure accountability for resolving system-performance issues. The practical result was limited leverage for the government even when the system failed to meet technical and operational needs.
The most striking example came at termination. When SSA stopped work on the NGTP effort, the agency still paid the vendor the remaining portion of the full $125M contract amount. Whatever the legal and operational considerations behind that decision, the message to the market was problematic: poor performance did not produce a proportionate financial consequence.
SSA’s Course Correction
SSA’s response illustrates an alternative approach. Rather than pursuing another large, fully specified replacement effort, the agency adopted a more incremental approach using cloud-native technology and more flexible contract mechanisms. A proof-of-concept deployment of Amazon Connect at a Pennsylvania call center allowed SSA to test the platform in live operating conditions before scaling further.
This approach introduced several disciplines that had been missing from NGTP. It reduced dependence on bespoke infrastructure, created an opportunity to measure performance under real conditions, and allowed the agency to collect operational evidence before broader rollout. Critically, assumptions were tested incrementally rather than embedded upfront. The agency also adopted Product Operating Model best practices: they stood up a cross-functional product team with a product manager, technical lead, design lead, and an SME lead who was responsible for state specific launches, training, and key metrics.
Early results suggested improvement. SSA’s Office of Inspector General reported that the agency’s telephone service handled substantially more callers in fiscal year 2025 and that reported average speed of answer improved. The subsequent administration leveraged the scalable platform to expand deployment across all field offices. At the same time, oversight and public reporting also highlighted the importance of careful metric design. Some reported gains did not fully reflect the total time beneficiaries waited for callbacks or to resolve their issues. That distinction is key: better performance frameworks depend not simply on more metrics, but on the right metrics.
Lessons for Outcome-Based Acquisition
The SSA case highlights several lessons:
- Complex systems cannot be fully specified in advance. Over-specification increases risk, and can lock programs into the wrong solution.
- Iterative delivery is a risk management tool. It surfaces integration, usability, security, and performance problems early enough to address them.
- Accountability must be tied to mission outcomes. Operational and customer experience results matter more than intermediate artifacts.
Governance matters as much as contract structure. Strong product ownership and leadership are essential. Critical to the successful turnaround was having a cross-functional “product quad” of product management, engineering, design, and domain expertise. In the NGTP case, requirements were largely defined within an infrastructure-oriented telecommunications function, leading to a solution optimized for technical components rather than end-to-end service outcomes. This organizational starting point constrained problem framing and limited the program’s ability to align delivery with user needs and mission performance.
An outcome-based model would have defined mission metrics such as first-contact resolution and total time to complete transactions, incorporated discovery phases, and tied continuation decisions to demonstrated performance. It also would have created a precedent for early adoption of critical monitoring tools used by leaders in the course correction, like integrating real-time customer experience telemetry into daily operations, which enabled continuous monitoring of user outcomes and rapid reprioritization of features to address emerging issues as they occur.
Finally, contract structure alone is not sufficient. Successful implementation depends on sustained leadership, technical judgment, and the institutional willingness to act on evidence. Several interviewees noted that meaningful progress accelerated only after leadership with prior agile and product delivery experience assumed responsibility for the effort. Acquisition structure can enable better outcomes, but it cannot substitute for leadership capable of making informed technical and operational decisions in complex environments.
Conclusion
Large-scale IT modernization is central to federal mission delivery. Traditional acquisition models remain effective in stable, well-defined environments but are poorly matched to software-intensive systems characterized by uncertainty, interdependence, and continuous change.
Outcome-based contracting provides a more effective framework for these conditions. It strengthens accountability by tying funding and continuation decisions to measurable performance, improves risk management through iterative delivery, and reorients acquisition toward public value. Rather than asking whether a contractor delivered what was specified, it asks whether the government achieved the mission results it needed.
Realizing this shift requires more than changes to contract structure. The authorities to pursue outcome-based approaches largely already exist, but incentives, funding constraints, and workforce capabilities continue to reinforce specification-driven models. Appropriations structures limit flexibility, oversight mechanisms emphasize compliance over performance, and many agencies lack the product management and data capabilities needed to define and act on outcome metrics. Addressing these constraints will require coordinated changes across budgeting, oversight, acquisition practice, and workforce development.
In the near term, IT modernization progress should be visible in concrete ways: contracts that tie option decisions and incentives to mission outcomes; programs operating with empowered Product Owners and real-time performance data; and evaluation frameworks that prioritize whether services are improving, not just whether requirements were met. Over time, this would mark a broader shift from managing compliance with plans to managing performance against outcomes.For technology and IT modernization efforts, the success of outcome-based contracting depends on alignment with product operating model practices, technical expertise, and sustained leadership. The central proposition of OBC is not less discipline, but better discipline—organized around measurable outcomes, empirical evidence, and the continuous identification and reduction of technical and operational risk.